{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"## Gravitational Waves\n\nGravitational waves are disturbances or ripples in the curvature of spacetime, generated by accelerated masses, that propagate as waves outward from their source at the speed of light. They were first proposed by Oliver Heaviside in 1893 and then later by Henri Poincaré in 1905 and subsequently predicted in 1916 by Albert Einstein on the basis of his general theory of relativity. Later he refused to accept gravitational waves. Gravitational waves transport energy as gravitational radiation, a form of radiant energy similar to electromagnetic radiation.Newton's law of universal gravitation, part of classical mechanics, does not provide for their existence, since that law is predicated on the assumption that physical interactions propagate instantaneously (at infinite speed) – showing one of the ways the methods of Newtonian physics are unable to explain phenomena associated with relativity.\n\nThe first indirect evidence for the existence of gravitational waves came in 1974 from the observed orbital decay of the Hulse–Taylor binary pulsar, which matched the decay predicted by general relativity as energy is lost to gravitational radiation. In 1993, Russell A. Hulse and Joseph Hooton Taylor Jr. received the Nobel Prize in Physics for this discovery. The first direct observation of gravitational waves was not made until 2015, when a signal generated by the merger of two black holes was received by the LIGO gravitational wave detectors in Livingston, Louisiana, and in Hanford, Washington. The 2017 Nobel Prize in Physics was subsequently awarded to Rainer Weiss, Kip Thorne and Barry Barish for their role in the direct detection of gravitational waves. \n\n \n\n## Challenge Context\n\nWhen scientists detected the first class of gravitational waves in 2015, they expected the discoveries to continue. There are four classes, yet at present only signals from merging black holes and neutron stars have been detected. Among those remaining are continuous gravitational-wave signals. These are weak yet long-lasting signals emitted by rapidly-spinning neutron stars. Imagine the mass of our Sun but condensed into a ball the size of a city and spinning over 1,000 times a second. The extreme compactness of these stars, composed of the densest material in the universe, could allow continuous waves to be emitted and then detected on Earth. There are potentially many continuous signals from neutron stars in our own galaxy and the current challenge for scientists is to make the first detection, and hopefully data science can help with this mission.\n\n
 \n\nThis image, taken from a 2021 paper by the LIGO-Virgo-KAGRA collaboration, shows the maximum amplitude of a continuous wave any of these neutron stars could emit without being found by the search analyses. Circled stars show results constraining the physical properties of specific neutron stars. Traditional approaches to detecting these weak and hard-to-find continuous signals are based on matched-filtering variants. Scientists create a bank of possible signal waveform templates and ask how correlated each waveform is with the measured noisy data. High correlation is consistent with the presence of a signal similar to that waveform. Due to the long duration of these signals, banks could easily contain hundreds of quintillions of templates; yet, with so many possible waveforms, scientists don’t have the computational power to use the approach without making approximations that weaken the sensitivity to the signals.\n\nG2Net is a network of Gravitational Wave, Geophysics and Machine Learning. Via an Action from COST (European Cooperation in Science and Technology), a funding agency for research and innovation networks, G2Net aims to create a broad network of scientists. From four different areas of expertise, namely GW physics, Geophysics, Computing Science and Robotics, these scientists have agreed on a common goal of tackling challenges in data analysis and noise characterization for GW detectors.","metadata":{}},{"cell_type":"markdown","source":"## Installing and importing necessary dependancies","metadata":{}},{"cell_type":"code","source":"!pip install riroriro\n!pip install visualkeras\n!pip install git+https://github.com/PyFstat/PyFstat@python37","metadata":{"_kg_hide-output":true,"scrolled":true,"execution":{"iopub.status.busy":"2022-10-29T23:24:14.832413Z","iopub.execute_input":"2022-10-29T23:24:14.832935Z","iopub.status.idle":"2022-10-29T23:25:37.249228Z","shell.execute_reply.started":"2022-10-29T23:24:14.832851Z","shell.execute_reply":"2022-10-29T23:25:37.247669Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import os\nimport h5py\nimport gc\nimport glob\nimport math\nimport random\nimport warnings\nimport pyfstat\nimport librosa\nimport librosa.display\nimport numpy as np\nimport pandas as pd\nimport seaborn as sns\nimport visualkeras\nimport riroriro.inspiralfuns as ins\nimport riroriro.mergerfirstfuns as me1\nimport riroriro.matchingfuns as mat\nimport riroriro.mergersecondfuns as me2\nimport tensorflow as tf\nfrom scipy.signal import istft\nfrom tensorflow.keras import regularizers\nfrom tensorflow.keras import layers\nimport tensorflow_addons as tfa\n\nfrom pathlib import Path\nfrom scipy import stats\nfrom tqdm.notebook import tqdm\nfrom scipy import signal\nimport matplotlib.pyplot as plt\nfrom IPython.display import HTML, display\nfrom tensorflow.keras.utils import plot_model\nfrom sklearn.model_selection import train_test_split\n\nsns.set_theme()\n%matplotlib inline \nwarnings.filterwarnings('ignore')\ndisplay(HTML(''))","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:37.252275Z","iopub.execute_input":"2022-10-29T23:25:37.252724Z","iopub.status.idle":"2022-10-29T23:25:55.916016Z","shell.execute_reply.started":"2022-10-29T23:25:37.252677Z","shell.execute_reply":"2022-10-29T23:25:55.914869Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"DATA_PATH = Path('../input/g2net-detecting-continuous-gravitational-waves')\nTRAIN_PATH = DATA_PATH/'train'\nTEST_PATH = DATA_PATH/'test'\ntrain_example_with_signal_path = TRAIN_PATH/'cc561e4fc.hdf5'\ntrain_example_without_signal_path = TRAIN_PATH/'fb6db0d08.hdf5'","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:55.91763Z","iopub.execute_input":"2022-10-29T23:25:55.918295Z","iopub.status.idle":"2022-10-29T23:25:55.926903Z","shell.execute_reply.started":"2022-10-29T23:25:55.918258Z","shell.execute_reply":"2022-10-29T23:25:55.926039Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## HDF files exploration\n\nHierarchical Data Format (HDF) is a set of file formats (HDF4, HDF5) designed to store and organize large amounts of data. Originally developed at the U.S. National Center for Supercomputing Applications, it is supported by The HDF Group, a non-profit corporation whose mission is to ensure continued development of HDF5 technologies and the continued accessibility of data stored in HDF.\nIn keeping with this goal, the HDF libraries and associated tools are available under a liberal, BSD-like license for general use. HDF is supported by many commercial and non-commercial software platforms and programming languages. The freely available HDF distribution consists of the library, command-line utilities, test suite source, Java interface, and the Java-based HDF Viewer (HDFView).\nThe current version, HDF5, differs significantly in design and API from the major legacy version HDF4. \n\n## HDF5\n\n
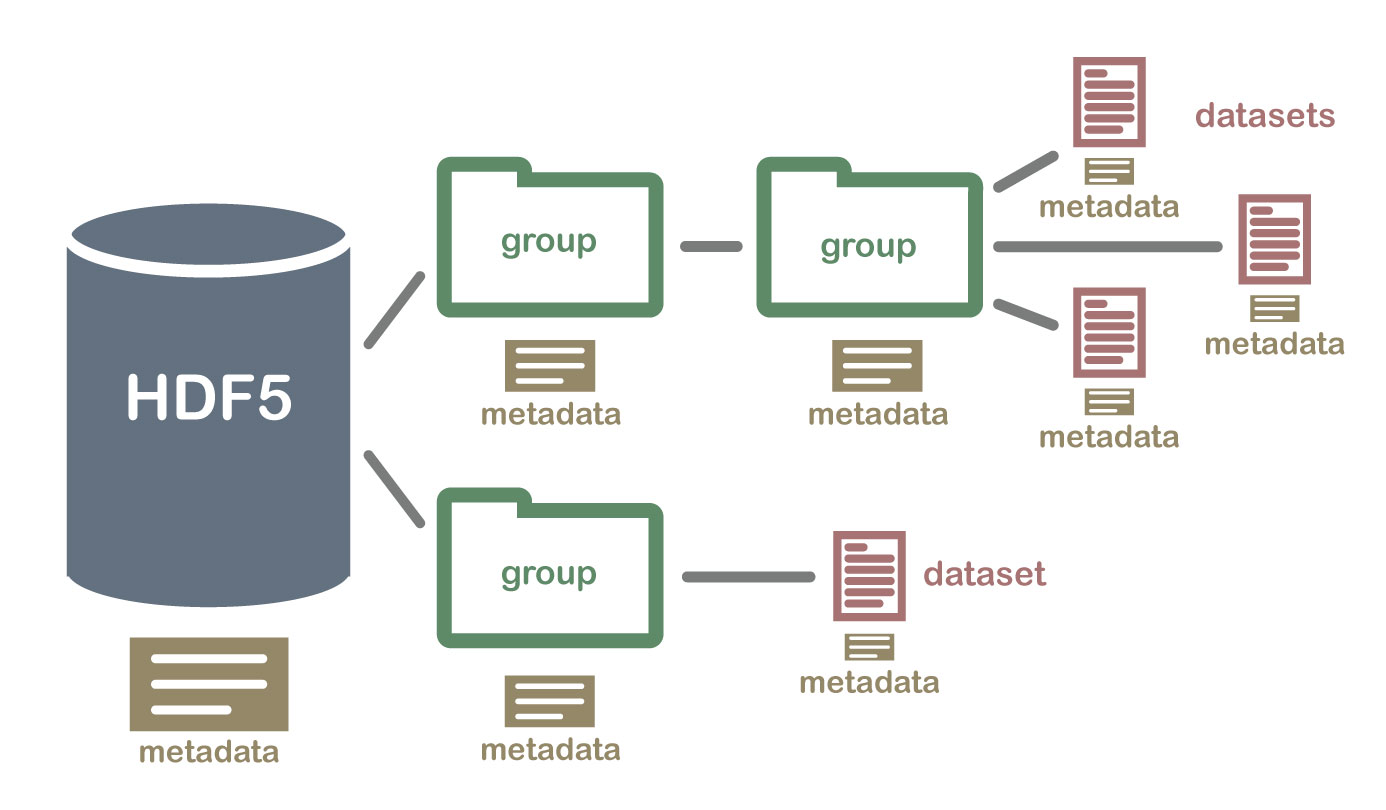 \n\nThe HDF5 format is designed to address some of the limitations of the HDF4 library, and to address current and anticipated requirements of modern systems and applications. In 2002 it won an R&D 100 Award.\nHDF5 simplifies the file structure to include only two major types of object:\nHDF Structure Example\n\n* Datasets, which are typed multidimensional arrays\n* Groups, which are container structures that can hold datasets and other groups\n\n## Our dataset structures\n\n* ID is the top group of the HDF5 file and links the datapoint to it's label in the train_labels csv (group)\n* frequency_Hz contains the range frequencies measured by the dectors (dataset)\n* H1 contains the data for the LIGO Hanford decector (group)\n - SFTs is the Short-time Fourier Transforms amplitudes for each timestamp at each frequency (dataset)\n - timestamps contains the timestamps for the measurement (dataset)\n\n* L1 contains the data for the LIGO Livingston decector (group)\n - SFTs is the Short-time Fourier Transforms amplitudes for each timestamp at each frequency (dataset)\n - timestamps contains the timestamps for the measurement (dataset)\n \nFor good EDA check this great work of Edward Crookenden\n","metadata":{}},{"cell_type":"markdown","source":"## Loading meta data","metadata":{}},{"cell_type":"code","source":"labels_df = pd.read_csv(DATA_PATH/'train_labels.csv')\nlabels_df.head()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:55.935242Z","iopub.execute_input":"2022-10-29T23:25:55.935768Z","iopub.status.idle":"2022-10-29T23:25:55.977188Z","shell.execute_reply.started":"2022-10-29T23:25:55.93574Z","shell.execute_reply":"2022-10-29T23:25:55.97612Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(6,4))\nsns.barplot(['Train', 'Test'], [len(os.listdir(TRAIN_PATH)), len(os.listdir(TEST_PATH))]);\nplt.title(f'Train test split', fontsize=12)\nplt.ylabel('Count', fontsize=12)\nplt.xlabel('Category', fontsize=12)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:55.978555Z","iopub.execute_input":"2022-10-29T23:25:55.979556Z","iopub.status.idle":"2022-10-29T23:25:56.492278Z","shell.execute_reply.started":"2022-10-29T23:25:55.979517Z","shell.execute_reply":"2022-10-29T23:25:56.49135Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"This is unusual as we most of the time see data splits as 80:20 but in our case it is 1:16 which indicates that the competition creators are encouraging participants to generate their own data.","metadata":{}},{"cell_type":"code","source":"label_count = labels_df['target'].value_counts()\nplt.figure(figsize=(10,8))\nsns.barplot(label_count.index, label_count.values, alpha=0.7)\nplt.title(f'Frequency of labels in training data', fontsize=12)\nplt.ylabel('Count', fontsize=12)\nplt.xlabel('label', fontsize=12)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:56.493821Z","iopub.execute_input":"2022-10-29T23:25:56.494452Z","iopub.status.idle":"2022-10-29T23:25:56.726266Z","shell.execute_reply.started":"2022-10-29T23:25:56.494411Z","shell.execute_reply":"2022-10-29T23:25:56.725317Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"The target labels; 1 if the data contains the presence of a gravitational wave, 0 otherwise. (Please note the presence of a small number of files labeled -1. Physicists are currently unable to determine the status of these files.)","metadata":{}},{"cell_type":"markdown","source":"## Spectogram analysis\n\nA spectrogram is a visual representation of the spectrum of frequencies of a signal as it varies with time. When applied to an audio signal, spectrograms are sometimes called sonographs, voiceprints, or voicegrams. When the data are represented in a 3D plot they may be called waterfall displays.\n\n
 \n\nSpectrograms are used extensively in the fields of music, linguistics, sonar, radar, speech processing, seismology, and others. Spectrograms of audio can be used to identify spoken words phonetically, and to analyse the various calls of animals.\nA spectrogram can be generated by an optical spectrometer, a bank of band-pass filters, by Fourier transform or by a wavelet transform (in which case it is also known as a scaleogram or scalogram).\nScaleograms from the DWT and CWT for an audio sample\nA spectrogram is usually depicted as a heat map, i.e., as an image with the intensity shown by varying the colour or brightness. ","metadata":{}},{"cell_type":"code","source":"def extract_data_from_hdf5(path, labels):\n '''\n Extracts data from hdf5 file and puts it into a dict. It also adds the label\n '''\n \n data = {}\n \n with h5py.File(path, \"r\") as f:\n\n ID_key = list(f.keys())[0]\n\n # Retrieve the frequency data\n data['freq'] = np.array(f[ID_key]['frequency_Hz'])\n\n # Retrieve the Livingston decector data\n data['L1_SFTs_amplitudes'] = np.array(f[ID_key]['L1']['SFTs'])\n data['L1_ts'] = np.array(f[ID_key]['L1']['timestamps_GPS'])\n\n # Retrieve the Hanford decector data\n data['H1_SFTs_amplitudes'] = np.array(f[ID_key]['H1']['SFTs'])\n data['H1_ts'] = np.array(f[ID_key]['H1']['timestamps_GPS'])\n \n # Get label from training labels if in training set\n data['label'] = labels.loc[labels.id==ID_key].target.item()\n \n return data","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:56.727766Z","iopub.execute_input":"2022-10-29T23:25:56.728105Z","iopub.status.idle":"2022-10-29T23:25:56.736959Z","shell.execute_reply.started":"2022-10-29T23:25:56.728071Z","shell.execute_reply":"2022-10-29T23:25:56.735748Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def extract_data_from_hdf5_reduced(path, labels):\n '''\n Extracts data from hdf5 file and puts it into a dict. It also adds the label\n '''\n \n data = {}\n \n with h5py.File(path, \"r\") as f:\n\n ID_key = list(f.keys())[0]\n\n # Retrieve the frequency data\n data['id'] = ID_key\n data['freq'] = np.array(f[ID_key]['frequency_Hz'])\n\n # Retrieve the Livingston decector data\n data['L1_ts'] = np.array(f[ID_key]['L1']['timestamps_GPS'])\n\n # Retrieve the Hanford decector data\n data['H1_ts'] = np.array(f[ID_key]['H1']['timestamps_GPS'])\n \n # Get label from training labels if in training set\n data['label'] = labels.loc[labels.id==ID_key].target.item()\n \n return data","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:56.738547Z","iopub.execute_input":"2022-10-29T23:25:56.738962Z","iopub.status.idle":"2022-10-29T23:25:56.754098Z","shell.execute_reply.started":"2022-10-29T23:25:56.738927Z","shell.execute_reply":"2022-10-29T23:25:56.753221Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def plot_spectograms(data):\n '''\n Shows the real and imaginary amplitudes of the SFTs as spectograms for both detectors\n '''\n \n fig, ax = plt.subplots(2, 2, figsize=(16, 10))\n fig.suptitle(f\"Label {data['label']}\")\n\n for ind, detector in enumerate(['L1', 'H1']):\n ax[ind][0].set(xlabel=\"Timestamps [GPS]\",\n ylabel=\"Frequency [Hz]\",\n title=f\"{detector} - Real part\")\n ax[ind][1].set(xlabel=\"Timestamps [GPS]\",\n ylabel=\"Frequency [Hz]\",\n title=f\"{detector} - Imaginary part\")\n \n \n c0 = ax[ind][0].pcolormesh(data[f\"{detector}_ts\"], data['freq'],\n data[f\"{detector}_SFTs_amplitudes\"].real)\n c1 = ax[ind][1].pcolormesh(data[f\"{detector}_ts\"], data['freq'],\n data[f\"{detector}_SFTs_amplitudes\"].imag)\n \n fig.colorbar(c0, ax=ax[ind][0])\n fig.colorbar(c1, ax=ax[ind][1])\n \n plt.show()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:56.755485Z","iopub.execute_input":"2022-10-29T23:25:56.755993Z","iopub.status.idle":"2022-10-29T23:25:56.766615Z","shell.execute_reply.started":"2022-10-29T23:25:56.755956Z","shell.execute_reply":"2022-10-29T23:25:56.765793Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"data = extract_data_from_hdf5(train_example_with_signal_path, labels_df)\nplot_spectograms(data)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:25:56.771495Z","iopub.execute_input":"2022-10-29T23:25:56.771884Z","iopub.status.idle":"2022-10-29T23:26:01.820239Z","shell.execute_reply.started":"2022-10-29T23:25:56.771856Z","shell.execute_reply":"2022-10-29T23:26:01.818653Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"data = extract_data_from_hdf5(train_example_without_signal_path, labels_df)\nplot_spectograms(data)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:01.821743Z","iopub.execute_input":"2022-10-29T23:26:01.822191Z","iopub.status.idle":"2022-10-29T23:26:07.170185Z","shell.execute_reply.started":"2022-10-29T23:26:01.822154Z","shell.execute_reply":"2022-10-29T23:26:07.168376Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Time Domain Dataset Preparation","metadata":{}},{"cell_type":"markdown","source":"The STFT is invertible, that is, the original signal can be recovered from the transform by the inverse STFT. The most widely accepted way of inverting the STFT is by using the overlap-add (OLA) method, which also allows for modifications to the STFT complex spectrum. This makes for a versatile signal processing method, referred to as the overlap and add with modifications method. \n\nThe inverse Fourier transform of X(τ,ω) for τ fixed:\n\n
 ","metadata":{}},{"cell_type":"code","source":"data_s = extract_data_from_hdf5(train_example_with_signal_path, labels_df)\ndata_w_s = extract_data_from_hdf5(train_example_without_signal_path, labels_df)\namp1 = data_s['L1_SFTs_amplitudes']\nf1 = data_s['freq']\namp2 = data_w_s['L1_SFTs_amplitudes']\nf2 = data_w_s['freq']\nf_m1 = sum(f1)/len(f1)\nf_m2 = sum(f2)/len(f2)\nprint('Mean of label 1 signal frequency is {}'.format(f_m1))\nprint('Mean of label 0 signal frequency is {}'.format(f_m2))","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:07.171707Z","iopub.execute_input":"2022-10-29T23:26:07.17282Z","iopub.status.idle":"2022-10-29T23:26:08.210222Z","shell.execute_reply.started":"2022-10-29T23:26:07.172782Z","shell.execute_reply":"2022-10-29T23:26:08.209076Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"_, xrec1 = signal.istft(amp1, f_m1)\n_, xrec2 = signal.istft(amp2, f_m2)\nxrec1_r = signal.resample(xrec1, 16707)\nxrec2_r = signal.resample(xrec2, 16707)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:08.212016Z","iopub.execute_input":"2022-10-29T23:26:08.212476Z","iopub.status.idle":"2022-10-29T23:26:08.943907Z","shell.execute_reply.started":"2022-10-29T23:26:08.212433Z","shell.execute_reply":"2022-10-29T23:26:08.942733Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print('Signal size in frequency domain is {}'.format(amp1[0].shape[0]))\nprint('Signal size in Time domain is {}'.format(xrec1.shape[0]))\nprint('Signal size in Time domain(resamples) is {}'.format(xrec1_r.shape[0]))","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:08.945517Z","iopub.execute_input":"2022-10-29T23:26:08.946598Z","iopub.status.idle":"2022-10-29T23:26:08.955545Z","shell.execute_reply.started":"2022-10-29T23:26:08.94655Z","shell.execute_reply":"2022-10-29T23:26:08.954029Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"As it seems the original time domain sequence size is way too large that's why we will be resampling the signal in order to be able to deal with it during modeling. This will reduce tremendous amount of data informativity but will help the correct architecture to converge and also will be friendly when it comes to computational resources.","metadata":{}},{"cell_type":"code","source":"plt.figure(figsize=(20,10))\n\nplt.subplot(1, 2, 1)\nplt.suptitle('Signals in Time Domain', fontsize=10)\nplt.ylabel('Signal', fontsize=16)\nplt.xlabel('Time', fontsize=16)\n\nplt.plot(xrec1_r, label='Label 1 signal')\nplt.legend(loc='upper right')\n\nplt.subplot(1, 2, 2)\nplt.ylabel('Signal', fontsize=16)\nplt.xlabel('Time', fontsize=16)\n\nplt.plot(xrec2_r, label='Label 0 signal', c = 'darkred')\n\nplt.legend(loc='upper right')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:08.957305Z","iopub.execute_input":"2022-10-29T23:26:08.95801Z","iopub.status.idle":"2022-10-29T23:26:10.124382Z","shell.execute_reply.started":"2022-10-29T23:26:08.95797Z","shell.execute_reply":"2022-10-29T23:26:10.123407Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"%%time\ntime_df = pd.DataFrame()\nfor p in tqdm(os.listdir(TRAIN_PATH), total=len(os.listdir(TRAIN_PATH))):\n final_data = dict()\n data = extract_data_from_hdf5(DATA_PATH/'train'/p, labels_df)\n amp1 = data['L1_SFTs_amplitudes']\n amp2 = data['H1_SFTs_amplitudes']\n f = data['freq']\n label = data['label']\n f_m = sum(f)/len(f)\n _, xrec1 = signal.istft(amp1, f_m)\n _, xrec2 = signal.istft(amp2, f_m)\n xrec1_r = signal.resample(xrec1, 16707)\n xrec2_r = signal.resample(xrec2, 16707)\n final_data['L1_resampled_time'] = xrec1_r\n final_data['H1_resampled_time'] = xrec2_r\n final_data['label'] = label\n time_df = time_df.append(final_data, ignore_index=True)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:26:10.12571Z","iopub.execute_input":"2022-10-29T23:26:10.126399Z","iopub.status.idle":"2022-10-29T23:34:19.982023Z","shell.execute_reply.started":"2022-10-29T23:26:10.126321Z","shell.execute_reply":"2022-10-29T23:34:19.980657Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"time_df = time_df.sample(frac=1.0)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:19.983726Z","iopub.execute_input":"2022-10-29T23:34:19.984866Z","iopub.status.idle":"2022-10-29T23:34:19.995471Z","shell.execute_reply.started":"2022-10-29T23:34:19.984824Z","shell.execute_reply":"2022-10-29T23:34:19.994364Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"time_df.shape","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:19.997091Z","iopub.execute_input":"2022-10-29T23:34:19.997608Z","iopub.status.idle":"2022-10-29T23:34:20.006456Z","shell.execute_reply.started":"2022-10-29T23:34:19.997565Z","shell.execute_reply":"2022-10-29T23:34:20.004858Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"time_df.head()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:20.007922Z","iopub.execute_input":"2022-10-29T23:34:20.009071Z","iopub.status.idle":"2022-10-29T23:34:20.034517Z","shell.execute_reply.started":"2022-10-29T23:34:20.009031Z","shell.execute_reply":"2022-10-29T23:34:20.03329Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Dataset Exploration","metadata":{}},{"cell_type":"code","source":"%%time\ntrain_df = pd.DataFrame()\nfor p in tqdm(os.listdir(TRAIN_PATH), total=len(os.listdir(TRAIN_PATH))):\n data = extract_data_from_hdf5_reduced(DATA_PATH/'train'/p, labels_df)\n train_df = train_df.append(data, ignore_index=True)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:20.035965Z","iopub.execute_input":"2022-10-29T23:34:20.036646Z","iopub.status.idle":"2022-10-29T23:34:37.596745Z","shell.execute_reply.started":"2022-10-29T23:34:20.036607Z","shell.execute_reply":"2022-10-29T23:34:37.595682Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_df.head()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:37.598563Z","iopub.execute_input":"2022-10-29T23:34:37.599069Z","iopub.status.idle":"2022-10-29T23:34:37.630449Z","shell.execute_reply.started":"2022-10-29T23:34:37.599026Z","shell.execute_reply":"2022-10-29T23:34:37.629294Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_df = train_df.loc[train_df['label'] != -1]","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:37.632304Z","iopub.execute_input":"2022-10-29T23:34:37.632712Z","iopub.status.idle":"2022-10-29T23:34:37.641067Z","shell.execute_reply.started":"2022-10-29T23:34:37.632674Z","shell.execute_reply":"2022-10-29T23:34:37.639922Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Frequencies Distribution","metadata":{}},{"cell_type":"code","source":"plt.figure(figsize=(14,6))\nsns.histplot(x=list(np.hstack(train_df['freq'])), stat=\"density\", common_norm=False, bins=40, kde=True)\nplt.title('Histogram of the range of Frequencies detected');\nplt.xlabel('Frequency Hz')\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:37.644219Z","iopub.execute_input":"2022-10-29T23:34:37.644952Z","iopub.status.idle":"2022-10-29T23:34:38.698242Z","shell.execute_reply.started":"2022-10-29T23:34:37.644921Z","shell.execute_reply":"2022-10-29T23:34:38.697264Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Time stamps Distribution","metadata":{}},{"cell_type":"code","source":"fig, ax = plt.subplots(1,2, figsize=(24,8))\nfig.suptitle(f\"In the plots the distribution of timestamps for both classes are shown; 1 indicates a simulated CW present and 0 not present\", fontsize=16)\nsns.histplot(\n x=list(len(i) for i in train_df['L1_ts']),hue=train_df['label'],\n stat=\"density\", common_norm=False, bins=20, ax=ax[0], kde=True).set_title('Length of measurement for Livingston detector', fontsize=16);\n\nsns.histplot(\n x=list(len(i) for i in train_df['H1_ts']),hue= train_df['label'], \n stat=\"density\", common_norm=False, bins=20, ax=ax[1], kde=True).set_title('Length of measurement for Hanford detector', fontsize=16);","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:38.699664Z","iopub.execute_input":"2022-10-29T23:34:38.70239Z","iopub.status.idle":"2022-10-29T23:34:39.504266Z","shell.execute_reply.started":"2022-10-29T23:34:38.702357Z","shell.execute_reply":"2022-10-29T23:34:39.503293Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Simulating gravitational waves and evaluating their detectability in Python\n\nRiroriro is a Python package to simulate the gravitational waveforms of binary mergers of black holes and/or neutron stars, and calculate several properties of these mergers and waveforms, specifically relating to their observability by gravitational wave detectors.\"\n\n\"The gravitational waveform simulation of Riroriro is based upon the methods of Buskirk and Babiuc-Hamilton (2019), a paper which describes a computational implementation of an earlier theoretical gravitational waveform model by Huerta et al. (2017), using post-Newtonian expansions and an approximation called the implicit rotating source to simplify the Einstein field equations and simulate gravitational waves. Riroriro's calculation of signal-to-noise ratios (SNR) of gravitational wave events is based on the methods of Barrett et al. (2018), with the simpler gravitational wave model Findchirp (Allen et al. (2012)) being used for comparison and calibration in these calculations.\"\n\nLink for the paper\n\n#### cc. of GW simulation: this part was written by Geir Drange and presented by Marília Prata\n\n\n\n\n\"Riroriro is a set of Python modules containing functions to simulate the gravitational waveforms of mergers of black holes and/or neutron stars, and calculate several properties of these mergers and waveforms, specifically relating to their observability by gravitational wave detectors. Riroriro combines areas covered by previous gravitational wave models (such as gravitational wave simulation, SNR calculation, horizon distance calculation) into a single package with broader scope and versatility in Python, a programming language that is ubiquitous in astronomy. Aside from being a research tool, Riroriro is also designed to be easy to use and modify, and it can also be used as an educational tool for students learning about gravitational waves.\"\n\n\"The modules “inspiralfuns”, “mergerfirstfuns”, “matchingfuns”, “mergersecondfuns” and “gwexporter”, in that order, can be used to simulate the strain amplitude and frequency of a merger gravitational waveform. The module “snrcalculatorfuns” can compare such a simulated waveform to a detector noise spectrum to calculate a signal-to-noise ratio (SNR) for that signal for that detector. The module “horizondistfuns” calculates the horizon distance of a merger given its waveform, and the module “detectabilityfuns” evaluates the detectability of a merger given its SNR.\"\n\nMore information on the pip installation can be found here: https://pypi.org/project/riroriro/\n\nTutorials for Riroriro can be found here: https://github.com/wvanzeist/riroriro_tutorials\n\nFull documentation of each of the functions of Riroriro can be found here: https://wvanzeist.github.io/\n\nhttps://github.com/wvanzeist/riroriro\n","metadata":{}},{"cell_type":"code","source":"# Code by Geir Drange https://www.kaggle.com/code/mistag/reverse-engineering-create-clean-gw-signals\n\n# Parameters:\n# logMC: system mass (0.0-2.0)\n# q: mass ratio (0.1-1.0)\n# D: distance (Mpc)\n# merger_type: 'BH'=binary black hole merger, 'NS'=binary neutron star merger\n# flow: low frequency (Hz) \ndef gen_gw(logMc=1.4, q=0.8, D=100.0, flow=10.0, merger_type='BH'):\n M, eta = ins.get_M_and_eta(logMc=logMc,q=q)\n start_x = ins.startx(M,flow)\n end_x = ins.endx(eta,merger_type)\n x, xtimes, dt = ins.PN_parameter_integration(start_x,end_x,M,eta)\n realtimes = ins.inspiral_time_conversion(xtimes,M)\n i_phase, omega, freq = ins.inspiral_phase_freq_integration(x,dt,M)\n r, rdot = ins.radius_calculation(x,M,eta)\n A1, A2 = ins.a1_a2_calculation(r,rdot,omega,D,M,eta)\n i_Aorth, i_Adiag = ins.inspiral_strain_polarisations(A1,A2,i_phase)\n i_amp = ins.inspiral_strain_amplitude(i_Aorth,i_Adiag)\n i_time = realtimes\n i_omega = omega\n sfin, wqnm = me1.quasi_normal_modes(eta)\n alpha, b, C, kappa = me1.gIRS_coefficients(eta,sfin)\n fhat, m_omega = me1.merger_freq_calculation(wqnm,b,C,kappa)\n fhatdot = me1.fhat_differentiation(fhat)\n m_time = me1.merger_time_conversion(M)\n min_switch_ind = mat.min_switch_ind_finder(i_time,i_omega,m_time,m_omega)\n final_i_index = mat.final_i_index_finder(min_switch_ind,i_omega,m_omega)\n time_offset = mat.time_offset_finder(min_switch_ind,final_i_index,i_time,m_time)\n i_m_time, i_m_omega = mat.time_frequency_stitching(min_switch_ind,final_i_index,time_offset,i_time,i_omega,m_time,m_omega)\n i_m_freq = mat.frequency_SI_units(i_m_omega,M)\n m_phase = me2.merger_phase_calculation(min_switch_ind,final_i_index,i_phase,m_omega)\n i_m_phase = me2.phase_stitching(final_i_index,i_phase,m_phase)\n m_amp = me2.merger_strain_amplitude(min_switch_ind,final_i_index,alpha,i_amp,m_omega,fhat,fhatdot)\n i_m_amp = me2.amplitude_stitching(final_i_index,i_amp,m_amp)\n m_Aorth, m_Adiag = me2.merger_polarisations(final_i_index,m_amp,m_phase,i_Aorth)\n i_m_Aorth, i_m_Adiag = me2.polarisation_stitching(final_i_index,i_Aorth,i_Adiag,m_Aorth,m_Adiag)\n return np.array(i_m_time), np.array(i_m_Aorth), np.array(i_m_Adiag), np.array(i_m_freq)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:39.505937Z","iopub.execute_input":"2022-10-29T23:34:39.508628Z","iopub.status.idle":"2022-10-29T23:34:39.521268Z","shell.execute_reply.started":"2022-10-29T23:34:39.508587Z","shell.execute_reply":"2022-10-29T23:34:39.520357Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\"The function returns two waves that represent orthogonal/diagonal waves. The output timescale that is returned is non-linear, so to convert these signals into uniform sampled signals as in the dataset, we need to resample. The function below will resample the gravitational wave signals to 2048Hz. It is crude though, based on nearest sample, but good enough for studying spectrums. Interpolation would be more proper.\"","metadata":{}},{"cell_type":"code","source":"SR = 2048 # target sample rate (Hz)\n# Parameters:\n# dt: time series\n# amp: amplitude signal\n# seg: output sequence length (seconds)\ndef resample(dt, amp, seg=2.0):\n end = dt[-1]\n start = end - seg\n d = np.zeros(int(SR*seg))\n for i in range((int(SR*seg))):\n t = start + i/SR\n d[i] = amp[np.where(dt == dt[np.abs(dt-t).argmin()])[0][0]]\n return d","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:39.522896Z","iopub.execute_input":"2022-10-29T23:34:39.523706Z","iopub.status.idle":"2022-10-29T23:34:39.540181Z","shell.execute_reply.started":"2022-10-29T23:34:39.523667Z","shell.execute_reply":"2022-10-29T23:34:39.539358Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def plot_sig(dt, sig1, sig2=None, seg=2.0):\n end = dt[-1]\n start = end - seg\n plt.figure(1)\n plt.plot(dt, sig1)\n peak = np.max(np.abs(sig1))\n plt.axis([start,end,np.min(sig1)-peak/10,np.max(sig1)+peak/10])\n if sig2 is not None:\n plt.plot(dt, sig2)\n plt.xlabel('Time (s)')\n plt.ylabel('Strain amplitude')\n","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:39.541404Z","iopub.execute_input":"2022-10-29T23:34:39.542331Z","iopub.status.idle":"2022-10-29T23:34:39.554945Z","shell.execute_reply.started":"2022-10-29T23:34:39.542282Z","shell.execute_reply":"2022-10-29T23:34:39.553956Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Test signal generation","metadata":{}},{"cell_type":"code","source":"m_time, m_Aorth, m_Adiag, m_freq = gen_gw(logMc=1.4, q=0.2)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:34:39.564416Z","iopub.execute_input":"2022-10-29T23:34:39.564706Z","iopub.status.idle":"2022-10-29T23:36:14.681738Z","shell.execute_reply.started":"2022-10-29T23:34:39.564666Z","shell.execute_reply":"2022-10-29T23:36:14.680669Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### How Gravitational waves get detected\n\n\"When a gravitational wave passes by Earth, it squeezes and stretches space. LIGO can detect this squeezing and stretching. Each LIGO observatory has two “arms” that are each more than 2 miles (4 kilometers) long. A passing gravitational wave causes the length of the arms to change slightly. The observatory uses lasers, mirrors, and extremely sensitive instruments to detect these tiny changes.\"","metadata":{}},{"cell_type":"code","source":"fig = plt.figure(figsize=(16,8))\nplt.subplot(2, 1, 1)\nplot_sig(m_time, m_Aorth, m_Adiag, seg=2)\nplt.subplot(2, 1, 2)\nplot_sig(m_time, m_Aorth, m_Adiag, seg=.1)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:36:14.683278Z","iopub.execute_input":"2022-10-29T23:36:14.683886Z","iopub.status.idle":"2022-10-29T23:36:15.734154Z","shell.execute_reply.started":"2022-10-29T23:36:14.683848Z","shell.execute_reply":"2022-10-29T23:36:15.733238Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Resample the signal to 2048Hz (only the orthogonal part)","metadata":{}},{"cell_type":"code","source":"d1 = resample(m_time, m_Aorth, 2.0)\n\nfig = plt.figure(figsize=(16,16))\nplt.subplot(2, 2, 1)\nplot_sig(m_time, m_Aorth, seg=2)\nplt.title('Original')\nplt.subplot(2, 2, 2)\nplot_sig(m_time, m_Aorth, seg=.1)\nplt.title('Original (zoomed)')\nplt.subplot(2, 2, 3)\nplt.plot(d1)\nplt.title('Resampled to 2048Hz')\nplt.subplot(2, 2, 4)\nplt.plot(d1[-205:])\nplt.title('Resampled to 2048Hz (zoomed)');","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:36:15.735457Z","iopub.execute_input":"2022-10-29T23:36:15.736371Z","iopub.status.idle":"2022-10-29T23:36:33.887151Z","shell.execute_reply.started":"2022-10-29T23:36:15.73632Z","shell.execute_reply":"2022-10-29T23:36:33.886247Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Visualizing Frequency Vector","metadata":{}},{"cell_type":"code","source":"fig, ax = plt.subplots(figsize=(12,8))\nplt.plot(m_time, m_freq, label=\"Min: {}Hz, Max: {}Hz\".format(int(np.min(m_freq)), int(np.max(m_freq))))\npeak = np.max(np.abs(m_freq))\nplt.axis([m_time[-1] - 2.0 if m_time[-1] >= 2.0 else m_time[0], m_time[-1], 0 , np.max(m_freq)+peak/10])\nax.legend()\nplt.xlabel('Time (s)')\nplt.ylabel('Frequency (Hz)');","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:36:33.888472Z","iopub.execute_input":"2022-10-29T23:36:33.88944Z","iopub.status.idle":"2022-10-29T23:36:35.108855Z","shell.execute_reply.started":"2022-10-29T23:36:33.889403Z","shell.execute_reply":"2022-10-29T23:36:35.107771Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Visualizing spectrum in frequency domain using Constant-Q transform","metadata":{}},{"cell_type":"code","source":"hop_length = 64\nC = np.abs(librosa.cqt(d1/np.max(d1), sr=SR, hop_length=hop_length, fmin=8, filter_scale=0.8, bins_per_octave=12))\nfig, ax = plt.subplots(figsize=(6,6))\nimg = librosa.display.specshow(librosa.amplitude_to_db(C, ref=np.max),\n sr=SR*2, hop_length=hop_length, bins_per_octave=12, ax=ax)\nax.set_title('Constant-Q power spectrum');","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:36:35.110261Z","iopub.execute_input":"2022-10-29T23:36:35.110764Z","iopub.status.idle":"2022-10-29T23:36:36.084488Z","shell.execute_reply.started":"2022-10-29T23:36:35.110725Z","shell.execute_reply":"2022-10-29T23:36:36.083387Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Amplitude vs. Distance(Inverse square law verification)","metadata":{}},{"cell_type":"code","source":"hop_length = 64\n\nfig = plt.figure(figsize=(20,15))\ndist = [100., 200., 400.]\nfor m in range(len(dist)):\n m_time, m_Aorth, _, m_freq = gen_gw(logMc=1.4, q=0.2, D=dist[m])\n rd = resample(m_time, m_Aorth, 2.0)\n # time series\n ax = plt.subplot(len(dist), 3, 1+m*3)\n plt.plot(rd)\n plt.title('Signal (D={} Mpc)'.format(int(dist[m])))\n # zoomed times series (chirp)\n ax = plt.subplot(len(dist), 3, 2+m*3)\n plt.plot(rd[-205:])\n plt.title('Signal chirp (zoomed)')\n # Q-Transform\n ax = plt.subplot(len(dist), 3, 3+m*3)\n if m == 0:\n smax = np.max(rd)\n C = np.abs(librosa.cqt(rd/smax, sr=SR, hop_length=hop_length, fmin=8, filter_scale=0.8, bins_per_octave=12))\n if m == 0:\n Cmax = np.max(C)\n img = librosa.display.specshow(librosa.amplitude_to_db(C, ref=Cmax), # was np.max\n sr=SR*2, hop_length=hop_length, bins_per_octave=12, ax=ax)\n ax.set_title('Constant-Q power spectrum');","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:36:36.086303Z","iopub.execute_input":"2022-10-29T23:36:36.087611Z","iopub.status.idle":"2022-10-29T23:42:05.637185Z","shell.execute_reply.started":"2022-10-29T23:36:36.087564Z","shell.execute_reply":"2022-10-29T23:42:05.636224Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Why the surprising results?\n\nSurprisingly we can notice that gravitational waves amplitude doesn't follow the inverse square law but why?\n\nIn order to answer this question we have to explain the difference between monopolic, diapolic and quadrapolic signals.\nFirst off, there are fundamental ways that light and gravitational waves are the same. They both:\n\n* do carry energy,\n* do reach infinite distances,\n* do spread out over space (in roughly a sphere) as you move farther away,\n* and will be detectable, at a certain distance, in proportion to the magnitude of the signal.\n\nBecause the geometry of space is the same for both light and gravitation, the difference between these two behaviors must lie in the nature of the signal that we can detect.\n\nTo understand that, we need to understand how gravity is a fundamentally different kind of force than electromagnetism. This will lead us to better understand how gravitational radiation (our gravitational waves) behave differently than electromagnetic radiation (light) when we allow it to propagate across the vast distances of intergalactic space.\n\n
 \n\nIf you want to create electromagnetic or gravitational radiation, how could you do it? The simplest way you could imagine — which (spoiler) doesn't work — would be to spontaneously create or destroy charge in a region of space. Having a charge pop into (or out of) existence would create radiation of a very specific type: monopole radiation. Monopole radiation is what happens when you have a change in the amount of charge that's present.\n\n
 \n\nWe cannot do this for either electromagnetism or gravitation, however. In electromagnetism, electric charge is conserved; in gravitation, mass/energy is conserved. The fact that we don't get monopole radiation is important for the stability of our Universe. If charge or mass could spontaneously be created or destroyed, existence would be extremely different!\n\nIf charge and mass/energy are conserved, then the next step is to either move your charges (or masses) rapidly back-and-forth, or to take charges of opposite signs and change the distance between them. This would create what we call dipole radiation, which changes the distribution of charge without changing the total amount of charge.\n\nIn electromagnetism, this creates radiation, because moving an electric charge back-and-forth changes the electric and magnetic fields together. This matters, because changing electric and magnetic fields that are mutually perpendicular to each other and in-phase if wis what an electromagnetic wave actually is. This is the simplest way to make light, and it radiates just like you're familiar with. The light carries energy, and the energy is what we detect, which is why objects appear dimmer as 1/r2 the farther away they are.\n\n
 \n\nIn gravity, however, freely moving a mass doesn't make gravitational radiation, because there's a conservation rule about masses in motion: the conservation of momentum. Similarly, separating masses doesn't make gravitational radiation either, because the center of mass remains constant. There's also a conservation rule about masses moving at a certain distance from the center of mass: the conservation of angular momentum.\n\nBecause energy, momentum, and angular momentum are conserved, you have to go past both monopole and dipole moments; you need a specific change in how the masses are distributed around their mutual center of mass. The simplest way to imagine this is to take two masses and have them mutually rotate around their center of mass, which results in what we call quadrupole radiation.\n\n
 \n\nThe amplitude of gravitational quadrupolar radiation falls off as 1/r, meaning the total energy falls off as 1/r2, just as it did for electromagnetic radiation. But this is where the fundamental difference between gravitation and electromagnetism comes in. There's a big difference between what you can physically detect for quadrupole and dipole radiation.\n\nFor electromagnetic (dipole) radiation, when the photons hit your detectors, they get absorbed, causing a change in the energy levels, and that change in energy — which remember, falls off as 1/r2 — is the signal you observe. That's why objects appear to dim according to an inverse square law.\n\nFor gravitational (quadrupole) radiation, however, it doesn't get directly absorbed in a detector. Rather, it causes objects to move towards or apart from one another in proportion to the amplitude of the wave. Even though the energy falls off as 1/r2, the amplitude only falls off as 1/r. That's why gravitational waves fall off according to a different law than electromagnetic waves.\n\n
 \n\nBut the amplitude, as we received it, compressed and expanded the entire Earth by about the diameter of three protons. The energy is huge and falls off as 1/r2, but we cannot detect energy for gravitational waves. We can only detect amplitude, which (thankfully) only falls off as 1/r, which is a very good thing. The amplitudes may be tiny, but if we can detect any signal at all, it's only a small step forward to detecting that same magnitude signal at any distance.\n\n For more check this! ","metadata":{}},{"cell_type":"markdown","source":"## Gravitational wave signal generation\n\nStandard CW signals can be parameterised in terms of two sets of parameters: the Doppler-modulation parameters λ and the amplitude parameters A.\n\nThe former encode how the frequency of a signal modulates due to its intrinsic frequency evolution and the movement of the Earth in the Solar system, while the latter describes the overall amplitude of a CW depending on the parameters of the source.\n\nFor a CW emmitted by a rapidly-spinning and isolated neutron star (NS), Doppler-modulation parameters include the frequency F0 and the linear spindown parameter F1, both taken at a reference time tref, and the sky position in terms of the right ascension Alpha and declination Delta angles of equatorial cordinates. Amplitude parameters, on the other hand, include the average amplitude of a CW signal h0, the initial phase of the signal phi, the polarization angle psi and (the cosine of) the inclination angle of the source cosi, which gives us the relative orientation of the NS with respect to the detector.\n\nAs described in the signal tutorial, the amplitude of a CW signal is usually expressed in terms of the noises's amplitude using depth D\nor signal-to-noise ratio (SNR) ρ. For our purposes, the former is essentially a quotient\n\n\n\nwhile the latter is a more involved expression wich also depends on the duration of the dataset at hand and the detector's response function. It is important to note, however, that ρ and D scale reciprocally: \"weak\" signals have a low SNR and a high depth (since they are \"buried deeper into the noise\" than a strong signal).\n\n## Data generation\n\nAs mebtioned before from the split of train and test datasets the challenge creators are encouraging participants to generate their own data but in out case we will keep it at the point of generating samples for explainations and the inbalanced classes problem will be solved with the class weight parameter while training.\n\nA specific sample requires of background noise and optionally a signal. In order to generate noise, one needs to specify a set of detectors (H1 or L1 in this case), the duration of the sample and the Amplitude Spectral Density of the noise sqrtSX. CW analyses are simple in this front, as sqrtSX is proportional to the (stationary) standard deviation of an underlying zero-mean Gaussian process.\n\nSample duration can be specified in two ways. If the sample contains contiguous data (i.e. the detector was taking science-quality data uninterrupted), one can simply specify the starting time and duration of the sample using tstart and duration. Data with gaps, on the other hand, can be generated by specifying a specific set of timestamps using the timestamps option.\n\nData is saved as a list of Short Fourier Transforms (SFTs). The duration and windowing of these SFTs can also be modified using Tsft, SFTWindowType and SFTWindowBeta. Most analyses tune Tsft around 1800 seconds order to ensure the power of a putative CW signal stays within a bin.\n\nFor more info check this notebook","metadata":{},"attachments":{"ff5aa71d-9612-41be-8dfd-23b875dec153.png":{"image/png":"iVBORw0KGgoAAAANSUhEUgAAAGgAAAA1CAYAAACtDK6IAAAABHNCSVQICAgIfAhkiAAAABl0RVh0U29mdHdhcmUAZ25vbWUtc2NyZWVuc2hvdO8Dvz4AAAiwSURBVHic7Zt5UFRXFoe/10CzigoIiIIiiAEEgwsat4kLCiJVLolLxmhMKpZjXMsEJ5iUZaLjjNFYiWXGTKWi5RiXmMQpFcEl6riiuCDghiBigziNuAFCb+/OH6IitEY6DXTo/v5qbl/eO+/+3jn3nnNvS0IIgQ2LRdHUBth4MTaBLBybQBaOfVMbYFkIyo4vIXFjFW19HZ/fq+wa6edU6Np05bVQz+e/5ZIDwSNnMTHKDclEi2wC1US+yf4DrZiyfCZ93EwdUvNiC3E1qMzYQXbnBHpZiDhgE+gpQs3BvZUMjO2AXVPbUgNbiKtGe3EXp/3i+bilEe8x3CV79yZ+OZZPmQwG2Z2wUZPoe3MracEf8m53hwazyyYQgLjDkd236TM1hDpDrVOR8vdlHPSbwrzFH9DWEUT5FbYsSSIpL5zZ3zfsENpCHKDPTeFY61gGetX2HpnCnV+z/v5g5kztTdvqhZ3k1oVR8a/iHBRJeAPPVzaBxAPSkguIio/AqfZ3chHHj+Ri8GhD61oj5eDsRqdXu9GmgdcTVi+QQbWHQw4xDG5rbKQNyDJoz2ziq63/JfPGPbTVlUv7yKkkjenY4AMoWXWxVFSQ/s2XFCQk8UaAsbWbQH1gGYlfp1FqECBJOLj7Ezl4ItMm9cdP2fAmNmuBRKWaEn0bvFsYj0Ny8Q6WbfVg1pz+uD83VMmUFZzh6PHTZGZlk31FxX2dPZ3+/CUrx3ds+CW5aKZU3tgvVs0YL2ZsyBE64z1ExreLxcYc498KuUqUlWvrNGtvJotFExLE6E9TxV3ZnBYbp1nOQZUXt7Bqcz446ijcv5tzD+v2ESWHSL3fj7hg48tkQ84WvvgxF32tdgefCMLb2uHi5YWrUHFw7SdMe2sx36f+xE8/fseSv/6DPYUGsz1LsxTIOWQM8z96j3dHReN69xjJR0t5No5ruZx8kjbxA/AwGtpkijOzKNLoqB3/xe3zZNz0Y2hMVxwU/gx6byQhcj4PPOMYO+4dxgRfY8+xImQzPUuzFAh7JUpJwr1PPK97azifvI8bNV5qcecoybeiGRn6nFle3CMrM5/SI5vZclaNtrpZq05n3fId8OY8JoQ+rnZLKOzbExLkgoSE0lGJpkpTR1iTH8VM17FMlGHEDQ8iZeM+dl8YzV8iHQE9eSlHaRGbiPfzFgaaHFQt3uGL5X6c2bSC+d89RHKww94tkNcmfM6inj48K630ZDvB3GlR8xYIBe2HxhP181ccST7JWxEDcS9LY1d+JG9OrJOWPsWpD9MSH30M/qgH43/jLg25Dm6eIa4GUut+xPf3pOL0Lg7e0qHaewC7mBj8zPHksorDG/eQqyvi6OZUTp7YzvaMu9zL+A/bz90xS5gzKQ+SK1Sc3p/KwdOXuHZdhbpMg0GWsFM64+7hQ8ArPRk4Ip5Br3hYhIvqr/3AvPnb0A0ZQ5c7ToxeOI6OlrSn8ALq+R7pKD7yTxIXfMtZQyf69fRB+0CHb8w8Pvt0AbOnjqJ3Oy1XD21j9YLZLPrlKlUNY3e9sA8cRly4Azf3pqJ5fTgd/iDiAPVJVGVRfm6tmDZ2ptiQ8yiB06StEOMTxoqlhypq9NOJkpNrxaw3EkTCqDliy3WDOfM2E5FF+fEVYvKM9eJK3dzToqmHB8mobzszbEES4zs7AIK7t9RoFN74t695wMIer+ipTB/ui6QvICPTPLH49yHh2ns6q5ZOJKTh9tYahHpMEXYEDp1M4JO/dRQWFCE7dSOoXe2YoSQoNBjljhI0mkc5QZPv8itc8WjV1EbUH9PncLmYq3kVKDqFEmLkhJKkkJBwwT/A2LEkwf1TG1izpwC9MfeSJCQkpMeq2vkx6P2p9Kuzodb8MVkg8eAKlwuh/dhwWtcZNz15l66ia92bARHG8g2JltFTSIo29e7Wg8kCPcw+x2WDD8N7+NcpuYv7p0g+XE7EhHF0d/6dFr4kCQkJjXMjE9m5c6dJ/2eiQFVcSM9C4z2IPkG1LqErYv+adeT1mMPSWN9Gy4RNHQBLxzSBKs5yOL2CtnF/IuTJFQRVRSfYunYzOZ1nsHRS1HMqxY/63ju5ntUpBbxUYV7hx5AZ7zPACucgEyoJem7v+xsz1xTSd+48YjzKKSm8yvm0E1zSdCZuymRGhLWyqMN/f2TqKZCe3K2JLPwhl0oUOLi0wjcojG7doojq3p1uwZ40wja9+RB6tFUatLIDLq5KiyxMNuszCS9EqNm/8nM2nizgjiGC6f9awggLDKGW+NI0DpI3Qz9czrRoF+zahRFaN1ewCKxXIAB9LlkXNXh2i8LfQidNqxbIcCOT7HtuREYFW8S2iDEs1a5GQFCanUWRfQd6qNazLKUU8fAWJe5D+WBuAsEv2HBtTKzXg0Q5FzLz0GtVFDkOZ+7Cj0n6ZBSe6RvYdsrIOa0mwno9SHeZzMs6vIfNYW5sB5wlEJWVVAqBi/x0YatVHeDfu1S08BSUlvkz8u0h+DdiLmG1HqTPz+ZiRUui+kbgWr2Ae3gpizwRSFgXl0cNopiUtam4xb/NuHFTGO11iG+SzXfm7WWwUoFk1BcuoLbvQtfOj4NIBedPnEcTGE1Pn0eKidKznMrzpL2vApDwaudFUVo66kbMHK1TIFHBpezrENSV0Gr3EeVnOXKmkk59++JXeYp169MpLymmRKFE+ThFUiqxK7mF2nwne38T6xRIl8OFHAN+XcPxrB58w/VL5GgD6NWzDcW/HkYXHoaTTodOoXi6cQhQVUmVzYMaFvGghNsE0Df66S+67YMGEBMqc2bDSrZVxTKxpysKJxcchXj2YKKTM06NWHSwylWc5BXLZxtjn210DmXC0tVMqNEkWnnQ2nDrya/qhEaDzjMAr0Z8ra3Sg14Wyas70YH/49oNPWCgOL8Iv9698G3EUbPeavZLolX9yvqf82jh58iduz7ETYmlUyNWGWwCWTi2EGfh2ASycGwCWTj/B2/UBlT0NfMCAAAAAElFTkSuQmCC"}}},{"cell_type":"code","source":"# Generate signals with parameters drawn from a specific population\nnum_signals = 2\n\n# These parameters describe background noise and data format\nwriter_kwargs = {\n \"tstart\": 1238166018,\n \"duration\": 4 * 30 * 86400, \n \"detectors\": \"H1,L1\", \n \"sqrtSX\": 1e-23, \n \"Tsft\": 1800, \n \"SFTWindowType\": \"tukey\", \n \"SFTWindowBeta\": 0.01,\n }","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:05.638779Z","iopub.execute_input":"2022-10-29T23:42:05.639361Z","iopub.status.idle":"2022-10-29T23:42:05.645519Z","shell.execute_reply.started":"2022-10-29T23:42:05.639311Z","shell.execute_reply":"2022-10-29T23:42:05.644356Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# This class allows us to sample signal parameters from a specific population.\n# Implicitly, sky positions are drawn uniformly across the celestial sphere.\n# PyFstat also implements a convenient set of priors to sample a population\n# of isotropically oriented neutron stars.\nsignal_parameters_generator = pyfstat.AllSkyInjectionParametersGenerator(\n priors={\n \"tref\": writer_kwargs[\"tstart\"],\n \"F0\": {\"uniform\": {\"low\": 100.0, \"high\": 100.1}},\n \"F1\": lambda: 10**stats.uniform(-12, 4).rvs(),\n \"F2\": 0,\n \"h0\": lambda: writer_kwargs[\"sqrtSX\"] / stats.uniform(1, 10).rvs(),\n **pyfstat.injection_parameters.isotropic_amplitude_priors,\n },\n)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:05.647054Z","iopub.execute_input":"2022-10-29T23:42:05.647714Z","iopub.status.idle":"2022-10-29T23:42:05.661774Z","shell.execute_reply.started":"2022-10-29T23:42:05.647668Z","shell.execute_reply":"2022-10-29T23:42:05.66087Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"snrs = np.zeros(num_signals)\n\nfor ind in range(num_signals):\n\n # Draw signal parameters.\n # Noise can be drawn by setting `params[\"h0\"] = 0\n params = signal_parameters_generator.draw()\n writer_kwargs[\"outdir\"] = f\"PyFstat_example_data_ensemble/Signal_{ind}\"\n writer_kwargs[\"label\"] = f\"Signal_{ind}\"\n \n writer = pyfstat.Writer(**writer_kwargs, **params)\n writer.make_data()\n \n # SNR can be compute from a set of SFTs for a specific set\n # of parameters as follows:\n snr = pyfstat.SignalToNoiseRatio.from_sfts(\n F0=writer.F0, sftfilepath=writer.sftfilepath\n )\n squared_snr = snr.compute_snr2(\n Alpha=writer.Alpha, \n Delta=writer.Delta,\n psi=writer.psi,\n phi=writer.phi, \n h0=writer.h0,\n cosi=writer.cosi\n )\n snrs[ind] = np.sqrt(squared_snr)\n \n # Data can be read as a numpy array using PyFstat\n frequency, timestamps, amplitudes = pyfstat.utils.get_sft_as_arrays(\n writer.sftfilepath\n )\n \n fig, ax = plt.subplots(2, 2, figsize=(16, 10))\n fig.suptitle(f\"Signal {ind} - SNR: {snrs[ind]:.2f}\")\n for d_ind, detector in enumerate(amplitudes.keys()):\n ax[d_ind][0].set(xlabel=\"Timestamps [GPS]\",\n ylabel=\"Frequency [Hz]\",\n title=f\"{detector} - Real part\")\n ax[d_ind][1].set(xlabel=\"Timestamps [GPS]\",\n ylabel=\"Frequency [Hz]\",\n title=f\"{detector} - Imaginary part\")\n \n c0 = ax[d_ind][0].pcolormesh(timestamps[detector], frequency,\n amplitudes[detector].real)\n c1 = ax[d_ind][1].pcolormesh(timestamps[detector], frequency,\n amplitudes[detector].imag)\n \n fig.colorbar(c0, ax=ax[d_ind][0])\n fig.colorbar(c1, ax=ax[d_ind][1])\n plt.show()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:05.663528Z","iopub.execute_input":"2022-10-29T23:42:05.663937Z","iopub.status.idle":"2022-10-29T23:42:20.972499Z","shell.execute_reply.started":"2022-10-29T23:42:05.663885Z","shell.execute_reply":"2022-10-29T23:42:20.971201Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Modeling with LSTM in Time Domain\n\nLong short-term memory (LSTM) is an artificial neural network used in the fields of artificial intelligence and deep learning. Unlike standard feedforward neural networks, LSTM has feedback connections. Such a recurrent neural network (RNN) can process not only single data points (such as images), but also entire sequences of data (such as speech or video). For example, LSTM is applicable to tasks such as unsegmented, connected handwriting recognition, speech recognition, machine translation, robot control, video games, and healthcare. LSTM has become the most cited neural network of the 20th century.\n\n
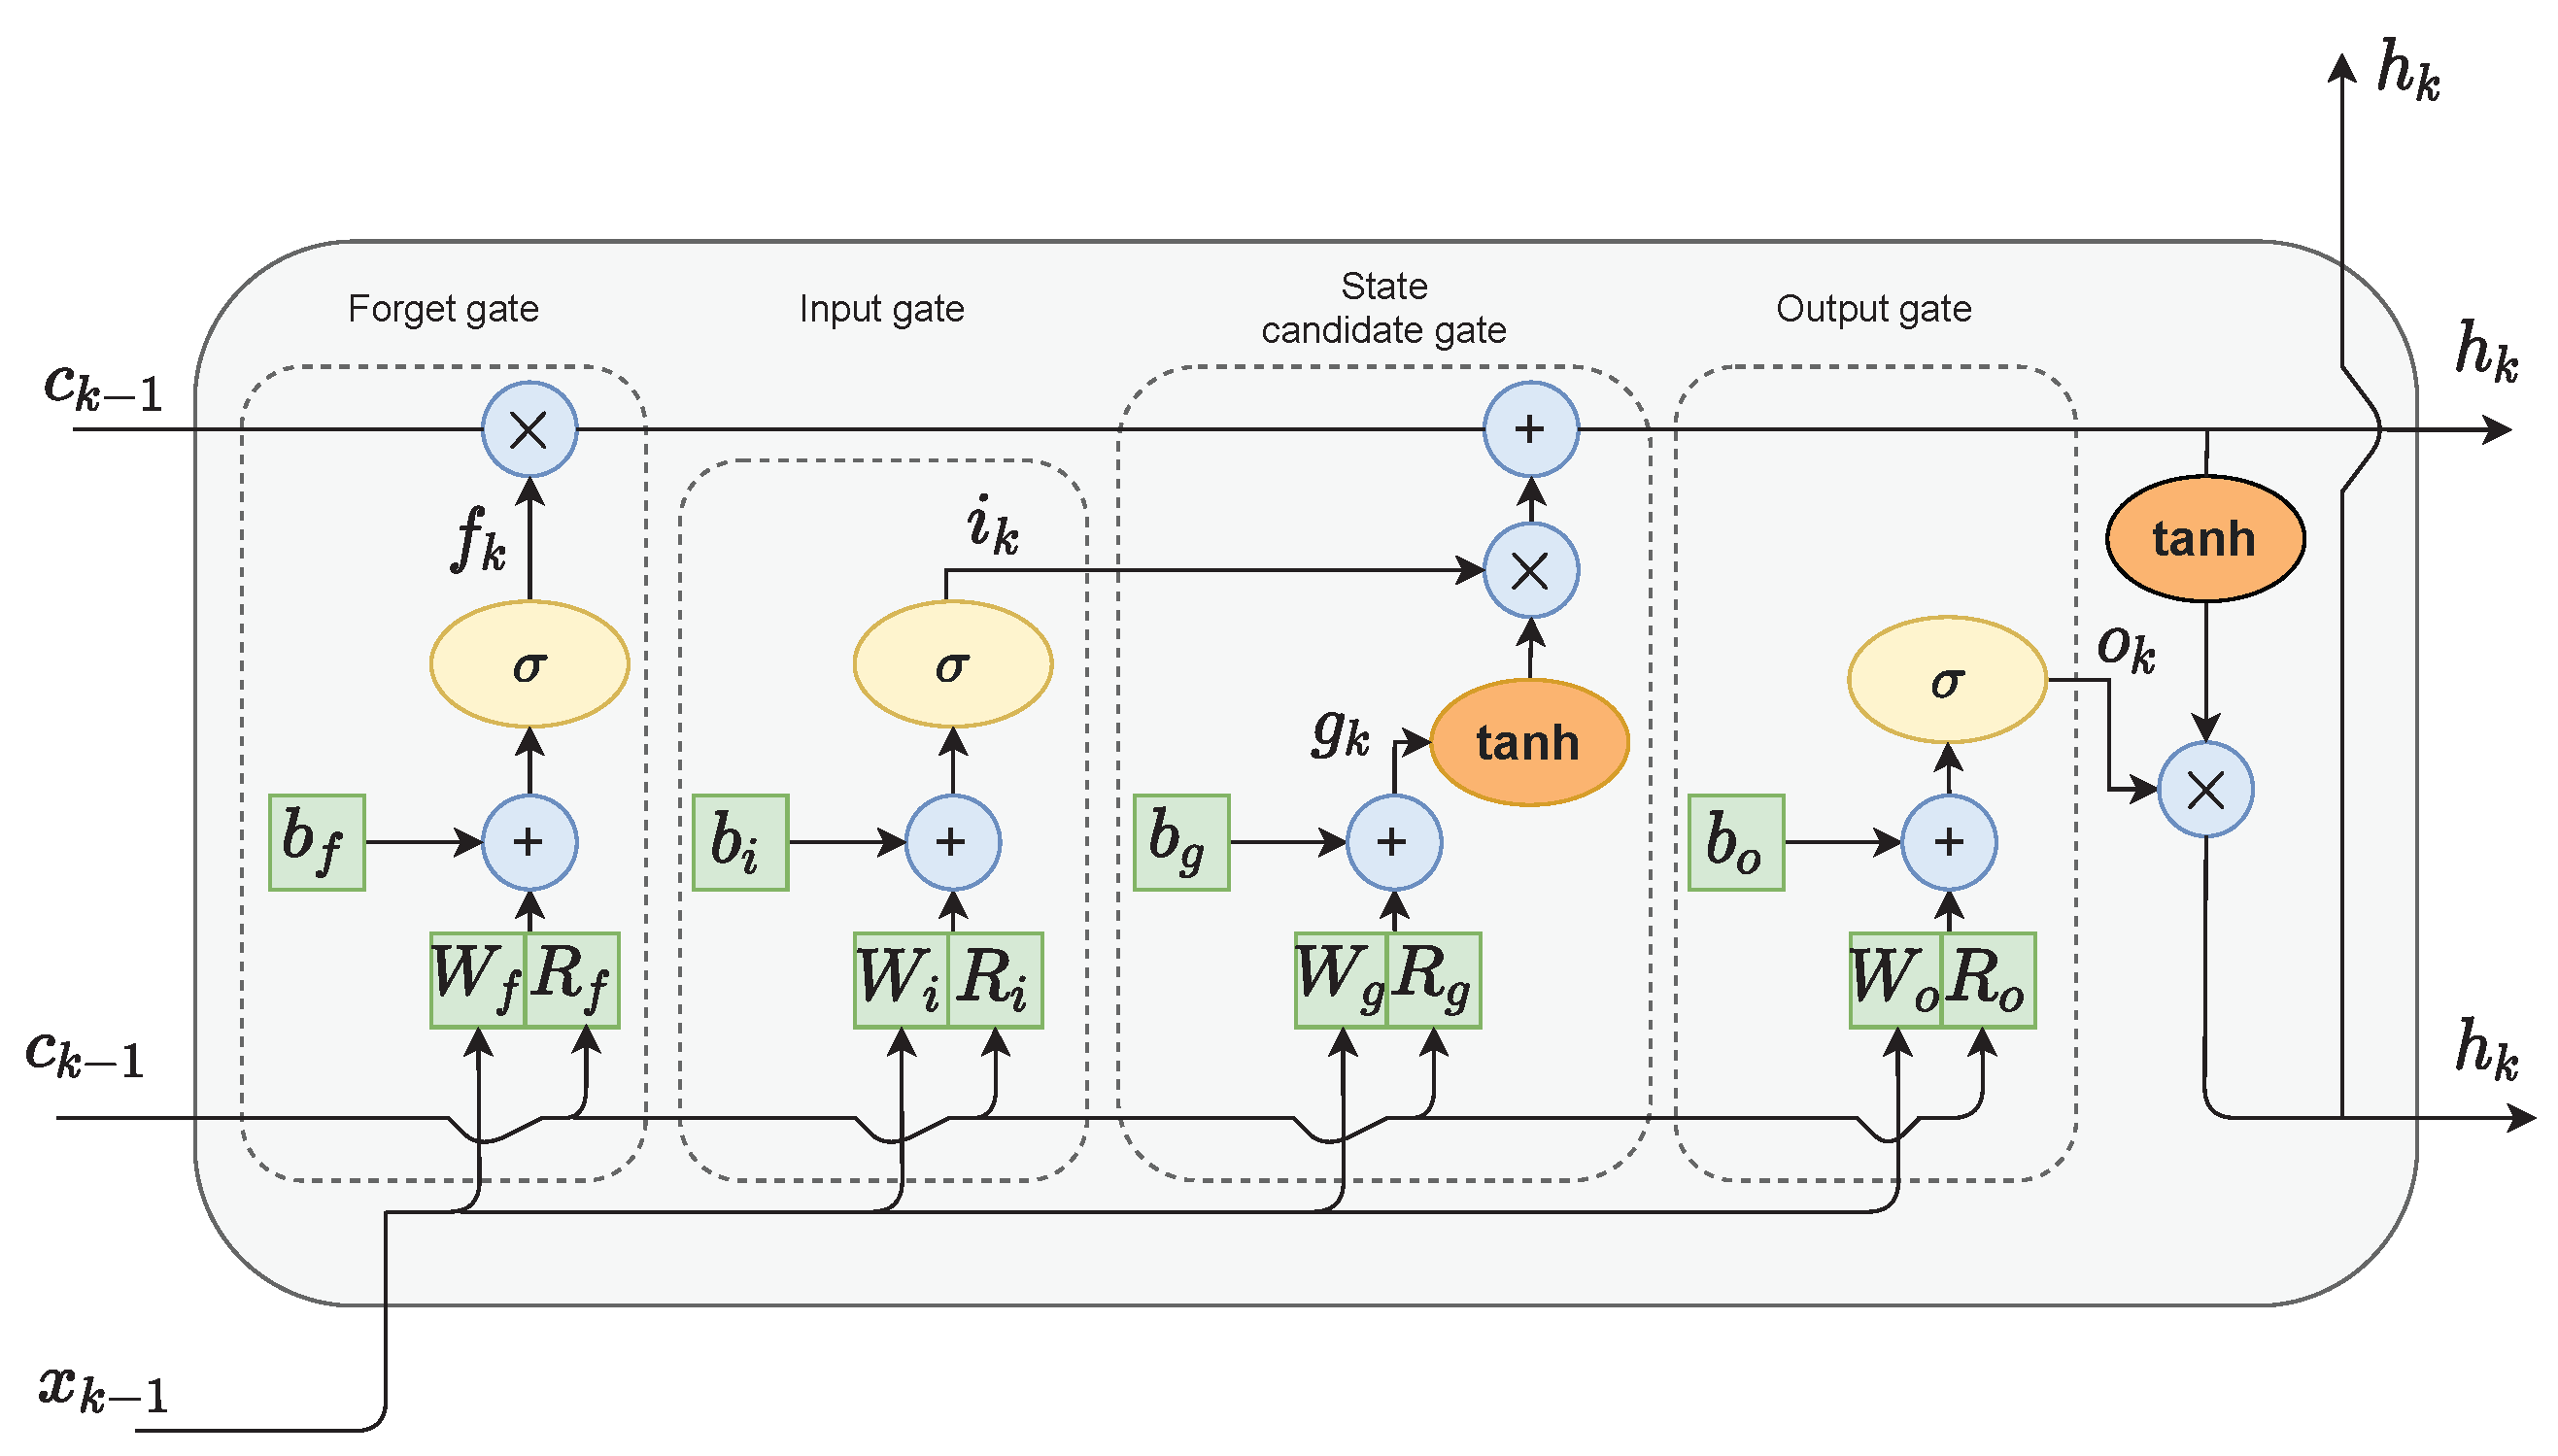 \n\nThe name of LSTM refers to the analogy that a standard RNN has both \"long-term memory\" and \"short-term memory\". The connection weights and biases in the network change once per episode of training, analogous to how physiological changes in synaptic strengths store long-term memories; the activation patterns in the network change once per time-step, analogous to how the moment-to-moment change in electric firing patterns in the brain store short-term memories. The LSTM architecture aims to provide a short-term memory for RNN that can last thousands of timesteps, thus \"long short-term memory\".\n\nA common LSTM unit is composed of a cell, an input gate, an output gate and a forget gate. The cell remembers values over arbitrary time intervals and the three gates regulate the flow of information into and out of the cell.\n\nLSTM networks are well-suited to classifying, processing and making predictions based on time series data, since there can be lags of unknown duration between important events in a time series. LSTMs were developed to deal with the vanishing gradient problem that can be encountered when training traditional RNNs. Relative insensitivity to gap length is an advantage of LSTM over RNNs, hidden Markov models and other sequence learning methods in numerous applications.\n\nThe compact forms of the equations for the forward pass of an LSTM cell with a forget gate are:\n\n
 ","metadata":{}},{"cell_type":"code","source":"X_l = np.asarray(time_df['L1_resampled_time'].to_list())\nX_h = np.asarray(time_df['H1_resampled_time'].to_list())\ny = np.asarray(time_df['label'].to_list())\n\nX_l = np.expand_dims(X_l, axis=1)\nX_h = np.expand_dims(X_h, axis=1)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:20.974458Z","iopub.execute_input":"2022-10-29T23:42:20.975215Z","iopub.status.idle":"2022-10-29T23:42:21.03403Z","shell.execute_reply.started":"2022-10-29T23:42:20.975171Z","shell.execute_reply":"2022-10-29T23:42:21.033028Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def create_lstm(x_input):\n \n lstm = tf.keras.Sequential([\n \n tf.keras.layers.LSTM(128, kernel_initializer='normal',input_shape=(1, X_l.shape[2]), return_sequences=True),\n tf.keras.layers.Dropout(0.2),\n \n tf.keras.layers.LSTM(128, kernel_initializer='normal', return_sequences=True),\n tf.keras.layers.Dropout(0.2),\n \n tf.keras.layers.LSTM(128, kernel_initializer='normal', return_sequences=True),\n tf.keras.layers.Dropout(0.2),\n \n tf.keras.layers.Dense(units=128, kernel_initializer='normal', activation='relu', \n kernel_regularizer=regularizers.L1L2(l1=1e-3, l2=1e-3), \n bias_regularizer=regularizers.L2(1e-2),\n activity_regularizer=regularizers.L2(1e-3)),\n tf.keras.layers.Dropout(0.5)\n ])\n \n features = lstm(x_input)\n x = layers.Dense(256, activation='relu')(features)\n return x","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:21.035481Z","iopub.execute_input":"2022-10-29T23:42:21.036075Z","iopub.status.idle":"2022-10-29T23:42:21.044876Z","shell.execute_reply.started":"2022-10-29T23:42:21.036033Z","shell.execute_reply":"2022-10-29T23:42:21.043776Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def get_lstm_model():\n # 1) Hanford \n h_input = tf.keras.layers.Input(shape=(1,X_l.shape[2]), name='x_h')\n # 2) Livingston \n l_input = tf.keras.layers.Input(shape=(1, X_l.shape[2]), name='x_l')\n \n h_out = create_lstm(h_input)\n l_out = create_lstm(l_input)\n\n \n # Concatenate embeddings\n x = tf.keras.layers.Concatenate()([h_out, l_out])\n x = tf.keras.layers.Dropout(0.5)(x)\n x = tf.keras.layers.Dense(128, kernel_initializer='normal')(x)\n x = tf.keras.layers.Dropout(0.5)(x)\n # Target prediction in range [0,1] with sigmoid activation\n output = tf.keras.layers.Dense(1, activation='sigmoid')(x)\n \n # Model\n inputs = [h_input, l_input]\n model = tf.keras.models.Model(inputs=inputs, outputs=output)\n \n optimizer = 'adam'\n\n model.compile(\n optimizer=optimizer,\n loss=tf.keras.losses.BinaryCrossentropy(from_logits=False),\n metrics = [\n tf.keras.metrics.AUC() ,\n ]\n )\n return model","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:21.046283Z","iopub.execute_input":"2022-10-29T23:42:21.047046Z","iopub.status.idle":"2022-10-29T23:42:21.057585Z","shell.execute_reply.started":"2022-10-29T23:42:21.047009Z","shell.execute_reply":"2022-10-29T23:42:21.056824Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"tf.keras.backend.clear_session()\ngc.collect()\nlstmmodel = get_lstm_model()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:21.058747Z","iopub.execute_input":"2022-10-29T23:42:21.05991Z","iopub.status.idle":"2022-10-29T23:42:29.997693Z","shell.execute_reply.started":"2022-10-29T23:42:21.059875Z","shell.execute_reply":"2022-10-29T23:42:29.996693Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(lstmmodel.summary())","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:29.999053Z","iopub.execute_input":"2022-10-29T23:42:30.00064Z","iopub.status.idle":"2022-10-29T23:42:30.01074Z","shell.execute_reply.started":"2022-10-29T23:42:30.000595Z","shell.execute_reply":"2022-10-29T23:42:30.009751Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plot_model(lstmmodel, show_shapes=True, show_layer_names=False, to_file=\"lstmmodel.png\")","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:42:30.012648Z","iopub.execute_input":"2022-10-29T23:42:30.013147Z","iopub.status.idle":"2022-10-29T23:42:32.083437Z","shell.execute_reply.started":"2022-10-29T23:42:30.013112Z","shell.execute_reply":"2022-10-29T23:42:32.082285Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"lstmhistory = lstmmodel.fit(\n x=[X_l, X_h],\n y=y,\n epochs = 50,\n validation_split=0.2,\n verbose = 1,\n )","metadata":{"scrolled":true,"execution":{"iopub.status.busy":"2022-10-29T23:42:32.085298Z","iopub.execute_input":"2022-10-29T23:42:32.086451Z","iopub.status.idle":"2022-10-29T23:43:08.331898Z","shell.execute_reply.started":"2022-10-29T23:42:32.086406Z","shell.execute_reply":"2022-10-29T23:43:08.330796Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(12,10))\n\nplt.suptitle('Optimizer : Adam, Loss : Binary CrossEntropy', fontsize=10)\nplt.ylabel('Loss', fontsize=16)\nplt.plot(lstmhistory.history['loss'], label='Training Loss')\nplt.plot(lstmhistory.history['val_loss'], label='Validatoin Loss')\nplt.legend(loc='upper right')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:08.334641Z","iopub.execute_input":"2022-10-29T23:43:08.335011Z","iopub.status.idle":"2022-10-29T23:43:08.817036Z","shell.execute_reply.started":"2022-10-29T23:43:08.33496Z","shell.execute_reply":"2022-10-29T23:43:08.815452Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Saving LSTM Model weights","metadata":{}},{"cell_type":"code","source":"lstmmodel.save_weights('lstmmodel.h5')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:08.82156Z","iopub.execute_input":"2022-10-29T23:43:08.822847Z","iopub.status.idle":"2022-10-29T23:43:09.005913Z","shell.execute_reply.started":"2022-10-29T23:43:08.822805Z","shell.execute_reply":"2022-10-29T23:43:09.004898Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Releasing Memory","metadata":{}},{"cell_type":"code","source":"del time_df, train_df","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:09.010581Z","iopub.execute_input":"2022-10-29T23:43:09.013429Z","iopub.status.idle":"2022-10-29T23:43:09.018893Z","shell.execute_reply.started":"2022-10-29T23:43:09.013387Z","shell.execute_reply":"2022-10-29T23:43:09.017553Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"gc.collect()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:09.023579Z","iopub.execute_input":"2022-10-29T23:43:09.024225Z","iopub.status.idle":"2022-10-29T23:43:09.402502Z","shell.execute_reply.started":"2022-10-29T23:43:09.024171Z","shell.execute_reply":"2022-10-29T23:43:09.401422Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Modeling with Vision Transformers(ViT) and Convolutional Neural Network(CNN) in Frequency Domain\n\nThe concept of Vision Transformer (ViT) is an extension of the original concept of Transformer. It is only the application of Transformer in the image domain with slight modification in the implementation in order to handle the different data modality. More specifically, a ViT uses different methods for tokenization and embedding. However, the generic architecture remains the same. An input image is split into a set of image patches, called visual tokens. The visual tokens are embedded into a set of encoded vectors of fixed dimension. The position of a patch in the image is embedded along with the encoded vector and fed into the transformer encoder network which is essentially the same as the one responsible for processing the text input. \n\n
 \n\nThere are multiple blocks in the ViT encoder and each block consists of three major processing elements: Layer Norm, Multi-head Attention Network (MSP) and Multi-Layer Perceptrons (MLP). Layer Norm keeps the training process on track and let model adapt to the variations among the training images. MSP is a network responsible for generation of attention maps from the given embedded visual tokens. These attention maps help network focus on most important regions in the image such as object(s). \n\n## Convolutional Neural Network\n\nIn deep learning, a convolutional neural network (CNN, or ConvNet) is a class of artificial neural network (ANN), most commonly applied to analyze visual imagery. CNNs are also known as Shift Invariant or Space Invariant Artificial Neural Networks (SIANN), based on the shared-weight architecture of the convolution kernels or filters that slide along input features and provide translation-equivariant responses known as feature maps. Counter-intuitively, most convolutional neural networks are not invariant to translation, due to the downsampling operation they apply to the input. They have applications in image and video recognition, recommender systems, image classification, image segmentation, medical image analysis, natural language processing, brain–computer interfaces, and financial time series.\n\n
 \n\nCNNs are regularized versions of multilayer perceptrons. Multilayer perceptrons usually mean fully connected networks, that is, each neuron in one layer is connected to all neurons in the next layer. The \"full connectivity\" of these networks make them prone to overfitting data. Typical ways of regularization, or preventing overfitting, include: penalizing parameters during training (such as weight decay) or trimming connectivity (skipped connections, dropout, etc.) CNNs take a different approach towards regularization: they take advantage of the hierarchical pattern in data and assemble patterns of increasing complexity using smaller and simpler patterns embossed in their filters. Therefore, on a scale of connectivity and complexity, CNNs are on the lower extreme. \n\n## General CNN vs. ViT talk\n\nThe differences between CNNs and Vision Transformers are many and lie mainly in their architectural differences.\nIn fact, CNNs achieve excellent results even with training based on data volumes that are not as large as those required by Vision Transformers.\nThis different behaviour seems to derive from the presence in the CNNs of some inductive biases that can be somehow exploited by these networks to grasp more quickly the particularities of the analysed images even if, on the other hand, they end up limiting them making it more complex to grasp global relations.\n\nOn the other hand, the Vision Transformers are free from these biases which leads them to be able to capture also global and wider range relations but at the cost of a more onerous training in terms of data.\nVision Transformers also proved to be much more robust to input image distortions such as adversarial patches or permutations.\nHowever, choosing one architecture over another is not always the wisest choice, and excellent results have been obtained in several Computer Vision tasks through hybrid architectures combining convolutional layers with Vision Transformers.","metadata":{}},{"cell_type":"markdown","source":"## Generating 360x360 Dataset by Mark Wijkhuizen","metadata":{}},{"cell_type":"code","source":"# Number of Samples in train dataset\nN_SAMPLES = len(labels_df)\n# Make 360x360 Patches\nTARGET_HEIGHT = 360\nTARGET_WIDTH = 360\nprint(f'TARGET_HEIGHT: {TARGET_HEIGHT}, TARGET_WIDTH: {TARGET_WIDTH}')\nIS_INTERACTIVE = os.environ['KAGGLE_KERNEL_RUN_TYPE'] == 'Interactive'\nINPUTS = ['x_h_r', 'x_h_i', 'x_l_r', 'x_l_i']","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:09.40411Z","iopub.execute_input":"2022-10-29T23:43:09.404482Z","iopub.status.idle":"2022-10-29T23:43:09.414189Z","shell.execute_reply.started":"2022-10-29T23:43:09.404453Z","shell.execute_reply":"2022-10-29T23:43:09.413007Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Get recording data type\n# A handful of complex128 recordings are present which will be ignored\ndef get_dtype(train_id):\n file = h5py.File(f'{TRAIN_PATH}/{train_id}.hdf5', 'r')[train_id]\n return file['H1']['SFTs'].dtype\n\nlabels_df['dtype'] = labels_df['id'].apply(get_dtype)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:09.416123Z","iopub.execute_input":"2022-10-29T23:43:09.417173Z","iopub.status.idle":"2022-10-29T23:43:17.431835Z","shell.execute_reply.started":"2022-10-29T23:43:09.417118Z","shell.execute_reply":"2022-10-29T23:43:17.430702Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"N_FLOAT64_SAMPLES = (labels_df['dtype'] == 'complex64').sum()\nprint(f'N_FLOAT64_SAMPLES: {N_FLOAT64_SAMPLES}')\n\ndisplay(labels_df['dtype'].value_counts().to_frame())","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:17.433367Z","iopub.execute_input":"2022-10-29T23:43:17.433789Z","iopub.status.idle":"2022-10-29T23:43:17.448475Z","shell.execute_reply.started":"2022-10-29T23:43:17.433749Z","shell.execute_reply":"2022-10-29T23:43:17.447136Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_dimension_rows = []\n\nfor train_id in tqdm(labels_df['id']): \n file = h5py.File(f'{TRAIN_PATH}/{train_id}.hdf5', 'r')[train_id]\n SFT_H = file['H1']['SFTs']\n SFT_L = file['L1']['SFTs']\n train_dimension_rows.append({\n 'id': train_id,\n 'H_height': SFT_H.shape[0],\n 'H_width': SFT_H.shape[1],\n 'L_height': SFT_L.shape[0],\n 'L_width': SFT_L.shape[1],\n }) ","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:17.450601Z","iopub.execute_input":"2022-10-29T23:43:17.451056Z","iopub.status.idle":"2022-10-29T23:43:26.042429Z","shell.execute_reply.started":"2022-10-29T23:43:17.451019Z","shell.execute_reply":"2022-10-29T23:43:26.041409Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"labels_df = labels_df.merge(pd.DataFrame(train_dimension_rows), on='id')\ndisplay(labels_df.head())","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:26.044388Z","iopub.execute_input":"2022-10-29T23:43:26.045019Z","iopub.status.idle":"2022-10-29T23:43:26.075166Z","shell.execute_reply.started":"2022-10-29T23:43:26.044978Z","shell.execute_reply":"2022-10-29T23:43:26.074175Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"labels_df[['H_height', 'L_height']].value_counts().to_frame(name='Count')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:26.076628Z","iopub.execute_input":"2022-10-29T23:43:26.076987Z","iopub.status.idle":"2022-10-29T23:43:26.093818Z","shell.execute_reply.started":"2022-10-29T23:43:26.076953Z","shell.execute_reply":"2022-10-29T23:43:26.092683Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Create target directories\n!rm -rf train_samples\n!mkdir -p train_samples/{x,target}\n!ls -l train_samples","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:26.09538Z","iopub.execute_input":"2022-10-29T23:43:26.095706Z","iopub.status.idle":"2022-10-29T23:43:29.324333Z","shell.execute_reply.started":"2022-10-29T23:43:26.095673Z","shell.execute_reply":"2022-10-29T23:43:29.323132Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# This large function actually generates the 360x360 patches\ndef get_train_stats():\n c = 0\n # Loop over all training samples\n for row_idx, row in tqdm(labels_df.iterrows(), total=N_SAMPLES): \n train_id = row['id']\n # Skip non-complex64 samples\n if row['dtype'] != 'complex64':\n continue\n \n # Read SFTs as numpy arrays\n with h5py.File(f'{TRAIN_PATH}/{train_id}.hdf5', 'r') as file:\n SFT_H = np.array(file[train_id]['H1']['SFTs'])\n SFT_L = np.array(file[train_id]['L1']['SFTs'])\n \n # Split into real and imaginary part\n SFT_H_SPLIT = SFT_H.view(np.float32).reshape([*SFT_H.shape, 2])\n SFT_L_SPLIT = SFT_L.view(np.float32).reshape([*SFT_L.shape, 2])\n # Transpose to get channel(real/imaginary) first\n SFT_H_SPLIT = np.transpose(SFT_H_SPLIT, [2,0,1])\n SFT_L_SPLIT = np.transpose(SFT_L_SPLIT, [2,0,1])\n \n # Create target array\n N = min(row['H_width'], row['L_width']) // TARGET_HEIGHT\n x = np.zeros(shape=[N, len(INPUTS), TARGET_HEIGHT, TARGET_HEIGHT], dtype=np.float32)\n # Get patches\n for offset in range(N):\n x[offset, 0] = SFT_H_SPLIT[0, :, offset * TARGET_HEIGHT:(offset + 1) * TARGET_HEIGHT]\n x[offset, 1] = SFT_H_SPLIT[1, :, offset * TARGET_HEIGHT:(offset + 1) * TARGET_HEIGHT]\n x[offset, 2] = SFT_L_SPLIT[0, :, offset * TARGET_HEIGHT:(offset + 1) * TARGET_HEIGHT]\n x[offset, 3] = SFT_L_SPLIT[1,:, offset * TARGET_HEIGHT:(offset + 1) * TARGET_HEIGHT]\n\n \n \n # Save patches and target\n np.save(f'./train_samples/x/{c}.npy', x)\n np.save(f'./train_samples/target/{c}.npy', np.array(row['target']))\n c += 1\n \n return c\n\nN_TRAIN_SAMPLES = get_train_stats()\nprint(f'N_TRAIN_SAMPLES: {N_TRAIN_SAMPLES}')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:43:29.326835Z","iopub.execute_input":"2022-10-29T23:43:29.327282Z","iopub.status.idle":"2022-10-29T23:46:26.395351Z","shell.execute_reply.started":"2022-10-29T23:43:29.327238Z","shell.execute_reply":"2022-10-29T23:46:26.394235Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"SAMPLE_IDXS = np.arange(len(glob.glob('./train_samples/target/*')))\nprint(f'SAMPLE_IDXS shape: {SAMPLE_IDXS.shape}')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:26.397646Z","iopub.execute_input":"2022-10-29T23:46:26.398412Z","iopub.status.idle":"2022-10-29T23:46:26.409026Z","shell.execute_reply.started":"2022-10-29T23:46:26.398372Z","shell.execute_reply":"2022-10-29T23:46:26.408008Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"random.shuffle(SAMPLE_IDXS)","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:26.41069Z","iopub.execute_input":"2022-10-29T23:46:26.411065Z","iopub.status.idle":"2022-10-29T23:46:27.45839Z","shell.execute_reply.started":"2022-10-29T23:46:26.41103Z","shell.execute_reply":"2022-10-29T23:46:27.457137Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Training dataset chooses a random 360x360 patch from a recording\ndef get_train_dataset(idxs, bs):\n while True:\n X = {\n 'x_h_r': np.zeros(shape=[bs,TARGET_HEIGHT, TARGET_WIDTH], dtype=np.float32),\n 'x_h_i': np.zeros(shape=[bs,TARGET_HEIGHT, TARGET_WIDTH], dtype=np.float32),\n 'x_l_r': np.zeros(shape=[bs,TARGET_HEIGHT, TARGET_WIDTH], dtype=np.float32),\n 'x_l_i': np.zeros(shape=[bs,TARGET_HEIGHT, TARGET_WIDTH], dtype=np.float32),\n }\n y = np.zeros(shape=[bs], dtype=np.int8)\n for i in range(bs):\n # Choose random file path\n index = np.random.choice(idxs, 1).squeeze()\n\n # Load x and choose random frame\n XX = np.load(f'./train_samples/x/{index}.npy')\n # Choose random patch\n patch_index = np.random.choice(len(XX), 1).squeeze()\n X['x_h_r'][i] = XX[patch_index, 0]\n X['x_h_i'][i] = XX[patch_index, 1]\n X['x_l_r'][i] = XX[patch_index, 2]\n X['x_l_i'][i] = XX[patch_index, 3]\n\n # Load target\n y[i] = np.load(f'./train_samples/target/{index}.npy')\n \n yield X, y\n ","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:27.459787Z","iopub.execute_input":"2022-10-29T23:46:27.460234Z","iopub.status.idle":"2022-10-29T23:46:28.184874Z","shell.execute_reply.started":"2022-10-29T23:46:27.460186Z","shell.execute_reply":"2022-10-29T23:46:28.183729Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Train batch statistics\ndef train_dataset_test():\n train_dataset = get_train_dataset(SAMPLE_IDXS, 64)\n X, y = next(train_dataset)\n for k in INPUTS:\n print(f'X {k} shape: {X[k].shape}, dtype: {X[k].dtype}', end=', ')\n print(f'X {k} mean: {X[k].mean():.2E}, std: {X[k].std():.2f}, min: {X[k].min():.2f}, max: {X[k].max():.2f}')\n print(f'y: {y}')\n \ntrain_dataset_test()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:28.186844Z","iopub.execute_input":"2022-10-29T23:46:28.187357Z","iopub.status.idle":"2022-10-29T23:46:34.173852Z","shell.execute_reply.started":"2022-10-29T23:46:28.187303Z","shell.execute_reply":"2022-10-29T23:46:34.17265Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Setting up general Parameters","metadata":{}},{"cell_type":"code","source":"learning_rate = 0.001\nweight_decay = 0.0001\nbatch_size = 32\nnum_epochs = 30\nimage_size = 360 # We'll resize input images to this size\npatch_size = 40 # Size of the patches to be extract from the input images\nnum_patches = (image_size // patch_size) ** 2\nprojection_dim = 64\nnum_heads = 4\ntransformer_units = [\n projection_dim * 2,\n projection_dim,\n] # Size of the transformer layers\ntransformer_layers = 8\nmlp_head_units = [2048, 1024] # Size of the dense layers of the final classifier","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:34.175263Z","iopub.execute_input":"2022-10-29T23:46:34.176172Z","iopub.status.idle":"2022-10-29T23:46:34.183417Z","shell.execute_reply.started":"2022-10-29T23:46:34.176131Z","shell.execute_reply":"2022-10-29T23:46:34.182333Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Implement MLP","metadata":{}},{"cell_type":"code","source":"def mlp(x, hidden_units, dropout_rate):\n for units in hidden_units:\n x = layers.Dense(units, activation=tf.nn.gelu)(x)\n x = layers.Dropout(dropout_rate)(x)\n return x","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:34.184787Z","iopub.execute_input":"2022-10-29T23:46:34.18522Z","iopub.status.idle":"2022-10-29T23:46:34.201539Z","shell.execute_reply.started":"2022-10-29T23:46:34.185181Z","shell.execute_reply":"2022-10-29T23:46:34.200581Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Implement patch creation as a layer\n","metadata":{}},{"cell_type":"code","source":"class Patches(layers.Layer):\n def __init__(self, patch_size):\n super(Patches, self).__init__()\n self.patch_size = patch_size\n\n def call(self, images):\n batch_size = tf.shape(images)[0]\n patches = tf.image.extract_patches(\n images=images,\n sizes=[1, self.patch_size, self.patch_size, 1],\n strides=[1, self.patch_size, self.patch_size, 1],\n rates=[1, 1, 1, 1],\n padding=\"VALID\",\n )\n patch_dims = patches.shape[-1]\n patches = tf.reshape(patches, [batch_size, -1, patch_dims])\n return patches","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:34.202931Z","iopub.execute_input":"2022-10-29T23:46:34.203638Z","iopub.status.idle":"2022-10-29T23:46:34.215383Z","shell.execute_reply.started":"2022-10-29T23:46:34.2036Z","shell.execute_reply":"2022-10-29T23:46:34.214378Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(8, 8))\nimages = np.load(f'./train_samples/x/{np.random.choice(SAMPLE_IDXS, 1)[0]}.npy')[np.random.choice(len(np.load(f'./train_samples/x/{np.random.choice(SAMPLE_IDXS, 1)[0]}.npy')), 1).squeeze()]\nimage = images[0]\nplt.grid(False)\nplt.imshow(image)\n\nimg = tf.reshape(image, (1, 360, 360, 1))\nresized_image = tf.image.resize(\n tf.convert_to_tensor(img), size=(image_size, image_size)\n)\nprint(resized_image.shape)\npatches = Patches(patch_size)(resized_image)\nprint(f\"Image size: {image_size} X {image_size}\")\nprint(f\"Patch size: {patch_size} X {patch_size}\")\nprint(f\"Patches per image: {patches.shape[1]}\")\nprint(f\"Elements per patch: {patches.shape[-1]}\")\nn = int(np.sqrt(patches.shape[1]))\nplt.figure(figsize=(8, 8))\nfor i, patch in enumerate(patches[0]):\n ax = plt.subplot(n, n, i + 1)\n patch_img = tf.reshape(patch, (patch_size, patch_size, 1))\n plt.imshow(patch_img.numpy())\n plt.axis(\"off\")","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:34.216758Z","iopub.execute_input":"2022-10-29T23:46:34.217301Z","iopub.status.idle":"2022-10-29T23:46:41.088379Z","shell.execute_reply.started":"2022-10-29T23:46:34.217264Z","shell.execute_reply":"2022-10-29T23:46:41.087226Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Creating the patch encoder\n\nThe PatchEncoder layer will linearly transform a patch by projecting it into a vector of size projection_dim. In addition, it adds a learnable position embedding to the projected vector.\n","metadata":{}},{"cell_type":"code","source":"class PatchEncoder(tf.keras.layers.Layer):\n def __init__(self, num_patches, projection_dim):\n super(PatchEncoder, self).__init__()\n self.num_patches = num_patches\n self.projection = layers.Dense(units=projection_dim)\n self.position_embedding = layers.Embedding(\n input_dim=num_patches, output_dim=projection_dim\n )\n\n def call(self, patch):\n positions = tf.range(start=0, limit=self.num_patches, delta=1)\n encoded = self.projection(patch) + self.position_embedding(positions)\n return encoded","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:41.090011Z","iopub.execute_input":"2022-10-29T23:46:41.09104Z","iopub.status.idle":"2022-10-29T23:46:41.099268Z","shell.execute_reply.started":"2022-10-29T23:46:41.090998Z","shell.execute_reply":"2022-10-29T23:46:41.098378Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Building the ViT\n\nThe ViT model consists of multiple Transformer blocks, which use the layers.MultiHeadAttention layer as a self-attention mechanism applied to the sequence of patches. The Transformer blocks produce a [batch_size, num_patches, projection_dim] tensor, which is processed via a Dense head to produce the final output.\n\nUnlike the technique described in the paper, which prepends a learnable embedding to the sequence of encoded patches to serve as the image representation, all the outputs of the final Transformer block are reshaped with layers.Flatten() and used as the image representation input to the classifier head. Note that the layers.GlobalAveragePooling1D layer could also be used instead to aggregate the outputs of the Transformer block, especially when the number of patches and the projection dimensions are large.\n","metadata":{}},{"cell_type":"code","source":"def create_vit_classifier(x_input):\n \n inputs = tf.expand_dims(x_input, axis=-1)\n inputs = tf.tile(inputs, [1,1,1,3])\n # Augment data.\n # Create patches.\n patches = Patches(patch_size)(inputs)\n # Encode patches.\n encoded_patches = PatchEncoder(num_patches, projection_dim)(patches)\n\n # Create multiple layers of the Transformer block.\n for _ in range(transformer_layers):\n # Layer normalization 1.\n x1 = layers.LayerNormalization(epsilon=1e-6)(encoded_patches)\n # Create a multi-head attention layer.\n attention_output = layers.MultiHeadAttention(\n num_heads=num_heads, key_dim=projection_dim, dropout=0.1\n )(x1, x1)\n # Skip connection 1.\n x2 = layers.Add()([attention_output, encoded_patches])\n # Layer normalization 2.\n x3 = layers.LayerNormalization(epsilon=1e-6)(x2)\n # MLP.\n x3 = mlp(x3, hidden_units=transformer_units, dropout_rate=0.1)\n # Skip connection 2.\n encoded_patches = layers.Add()([x3, x2])\n\n # Create a [batch_size, projection_dim] tensor.\n representation = layers.LayerNormalization(epsilon=1e-6)(encoded_patches)\n representation = layers.Flatten()(representation)\n representation = layers.Dropout(0.5)(representation)\n # Add MLP.\n features = mlp(representation, hidden_units=mlp_head_units, dropout_rate=0.5)\n # Classify outputs.\n x = layers.Dense(256, activation='relu')(features)\n # Create the Keras model.\n return x","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:41.100582Z","iopub.execute_input":"2022-10-29T23:46:41.101262Z","iopub.status.idle":"2022-10-29T23:46:41.114481Z","shell.execute_reply.started":"2022-10-29T23:46:41.101211Z","shell.execute_reply":"2022-10-29T23:46:41.113365Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Building CNN based Model","metadata":{}},{"cell_type":"code","source":"arch = tf.keras.Sequential([\n \n tf.keras.layers.Conv2D(filters=64,kernel_size=(5,5),strides=(2,2), activation=\"relu\", padding=\"valid\",input_shape=(image_size,image_size,3)),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n tf.keras.layers.Conv2D(filters=32,kernel_size=(5,5),strides=(2,2), activation=\"relu\", padding=\"valid\"),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n \n tf.keras.layers.Conv2D(filters=64,kernel_size=(3,3),strides=(2,2), activation=\"relu\", padding=\"valid\",input_shape=(image_size,image_size,3)),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n tf.keras.layers.Conv2D(filters=32,kernel_size=(3,3),strides=(2,2), activation=\"relu\", padding=\"valid\"),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n \n tf.keras.layers.Flatten(),\n tf.keras.layers.Dense(units=512, activation='relu', \n kernel_regularizer=regularizers.L1L2(l1=1e-3, l2=1e-3), \n bias_regularizer=regularizers.L2(1e-2),\n activity_regularizer=regularizers.L2(1e-3)),\n])\ndef create_cnn(x_input):\n \n inputs = tf.expand_dims(x_input, axis=-1)\n inputs = tf.tile(inputs, [1,1,1,3])\n cnn = tf.keras.Sequential([\n \n tf.keras.layers.Conv2D(filters=64,kernel_size=(5,5),strides=(2,2), activation=\"relu\", padding=\"valid\",input_shape=(image_size,image_size,3)),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n tf.keras.layers.Conv2D(filters=32,kernel_size=(5,5),strides=(2,2), activation=\"relu\", padding=\"valid\"),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n \n tf.keras.layers.Conv2D(filters=64,kernel_size=(3,3),strides=(2,2), activation=\"relu\", padding=\"valid\",input_shape=(image_size,image_size,3)),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n tf.keras.layers.Conv2D(filters=32,kernel_size=(3,3),strides=(2,2), activation=\"relu\", padding=\"valid\"),\n tf.keras.layers.MaxPooling2D((2, 2)),\n tf.keras.layers.BatchNormalization(),\n \n tf.keras.layers.Flatten(),\n tf.keras.layers.Dense(units=512, activation='relu', \n kernel_regularizer=regularizers.L1L2(l1=1e-3, l2=1e-3), \n bias_regularizer=regularizers.L2(1e-2),\n activity_regularizer=regularizers.L2(1e-3)),\n ])\n features = cnn(inputs)\n x = layers.Dense(256, activation='relu')(features)\n return x","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:41.116203Z","iopub.execute_input":"2022-10-29T23:46:41.116929Z","iopub.status.idle":"2022-10-29T23:46:41.237232Z","shell.execute_reply.started":"2022-10-29T23:46:41.116893Z","shell.execute_reply":"2022-10-29T23:46:41.236362Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Functions to get the vit and cnn models","metadata":{}},{"cell_type":"code","source":"def get_vit_model():\n # 1) Hanford Real\n h_r_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_h_r')\n # 2) Hanford imaginary\n h_i_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_h_i')\n # 3) Livingston Real\n l_r_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_l_r')\n # 4) Livingston Imaginary\n l_i_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_l_i')\n \n # Get embedding from vit\n h_r_embed = create_vit_classifier(h_r_input)\n h_i_embed = create_vit_classifier(h_i_input)\n l_r_embed = create_vit_classifier(l_r_input)\n l_i_embed = create_vit_classifier(l_i_input)\n \n # Concatenate embeddings\n x = tf.keras.layers.Concatenate()([h_r_embed, h_i_embed, l_r_embed, l_i_embed])\n x = tf.keras.layers.Dropout(0.5)(x)\n x = tf.keras.layers.Dense(128)(x)\n x = tf.keras.layers.Dropout(0.5)(x)\n # Target prediction in range [0,1] with sigmoid activation\n output = tf.keras.layers.Dense(1, activation='sigmoid')(x)\n \n # Model\n inputs = [h_r_input, h_i_input, l_r_input, l_i_input]\n model = tf.keras.models.Model(inputs=inputs, outputs=output)\n \n optimizer = tfa.optimizers.AdamW(\n learning_rate=learning_rate, weight_decay=weight_decay\n )\n\n model.compile(\n optimizer=optimizer,\n loss=tf.keras.losses.BinaryCrossentropy(from_logits=False),\n metrics = [\n tf.keras.metrics.AUC(),\n ]\n )\n return model\n\n\ndef get_cnn_model():\n # 1) Hanford Real\n h_r_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_h_r')\n # 2) Hanford imaginary\n h_i_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_h_i')\n # 3) Livingston Real\n l_r_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_l_r')\n # 4) Livingston Imaginary\n l_i_input = tf.keras.layers.Input(shape=[TARGET_HEIGHT, TARGET_WIDTH], dtype=tf.float32, name='x_l_i')\n \n # Get embedding from cnn\n h_r_embed = create_cnn(h_r_input)\n h_i_embed = create_cnn(h_i_input)\n l_r_embed = create_cnn(l_r_input)\n l_i_embed = create_cnn(l_i_input)\n \n # Concatenate embeddings\n x = tf.keras.layers.Concatenate()([h_r_embed, h_i_embed, l_r_embed, l_i_embed])\n x = tf.keras.layers.Dropout(0.5)(x)\n x = tf.keras.layers.Dense(128)(x)\n x = tf.keras.layers.Dropout(0.5)(x)\n # Target prediction in range [0,1] with sigmoid activation\n output = tf.keras.layers.Dense(1, activation='sigmoid')(x)\n \n # Model\n inputs = [h_r_input, h_i_input, l_r_input, l_i_input]\n model = tf.keras.models.Model(inputs=inputs, outputs=output)\n \n optimizer = tfa.optimizers.AdamW(\n learning_rate=learning_rate, weight_decay=weight_decay\n )\n\n model.compile(\n optimizer=optimizer,\n loss=tf.keras.losses.BinaryCrossentropy(from_logits=False),\n metrics = [\n tf.keras.metrics.AUC(),\n ]\n )\n return model","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:41.238637Z","iopub.execute_input":"2022-10-29T23:46:41.23897Z","iopub.status.idle":"2022-10-29T23:46:41.257351Z","shell.execute_reply.started":"2022-10-29T23:46:41.238936Z","shell.execute_reply":"2022-10-29T23:46:41.256386Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Exploring ViT in action","metadata":{}},{"cell_type":"code","source":"tf.keras.backend.clear_session()\ngc.collect()\nmodel = get_vit_model()","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:41.260427Z","iopub.execute_input":"2022-10-29T23:46:41.260691Z","iopub.status.idle":"2022-10-29T23:46:45.234382Z","shell.execute_reply.started":"2022-10-29T23:46:41.260667Z","shell.execute_reply":"2022-10-29T23:46:45.233396Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(model.summary())","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:45.238251Z","iopub.execute_input":"2022-10-29T23:46:45.238568Z","iopub.status.idle":"2022-10-29T23:46:45.294947Z","shell.execute_reply.started":"2022-10-29T23:46:45.238541Z","shell.execute_reply":"2022-10-29T23:46:45.294024Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plot_model(model, show_shapes=True, show_layer_names=False, to_file='vitmodel.png')","metadata":{"execution":{"iopub.status.busy":"2022-10-29T23:46:45.296191Z","iopub.execute_input":"2022-10-29T23:46:45.296979Z","iopub.status.idle":"2022-10-29T23:46:48.073144Z","shell.execute_reply.started":"2022-10-29T23:46:45.296941Z","shell.execute_reply":"2022-10-29T23:46:48.071568Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Fitting training data(ViT)","metadata":{}},{"cell_type":"code","source":"class_weights = {0:1.5, 1:0.75}\nhistory = model.fit(\n get_train_dataset(SAMPLE_IDXS, batch_size),\n steps_per_epoch=N_TRAIN_SAMPLES // batch_size,\n epochs = num_epochs,\n class_weight=class_weights,\n verbose = 1,\n )","metadata":{"scrolled":true,"execution":{"iopub.status.busy":"2022-10-29T23:46:48.074999Z","iopub.execute_input":"2022-10-29T23:46:48.07565Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Saving Model(ViT) Weights","metadata":{}},{"cell_type":"code","source":"model.save_weights('g2net_vit.h5')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Exploring CNN in action","metadata":{}},{"cell_type":"code","source":"tf.keras.backend.clear_session()\ngc.collect()\ncnnmodel = get_cnn_model()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(cnnmodel.summary())","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plot_model(cnnmodel, show_shapes=True, show_layer_names=False, to_file='cnnmodel.png')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"visualkeras.layered_view(arch, legend=True)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"class_weights = {0:1.5, 1:0.75}\ncnnhistory = cnnmodel.fit(\n get_train_dataset(SAMPLE_IDXS, batch_size),\n steps_per_epoch=N_TRAIN_SAMPLES // batch_size,\n epochs = 10,\n class_weight=class_weights,\n verbose = 1,\n )","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Saving CNN weights","metadata":{}},{"cell_type":"code","source":"cnnmodel.save_weights('g2net_cnn.h5')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Binary Cross Entropy Loss Curve","metadata":{}},{"cell_type":"code","source":"plt.figure(figsize=(20,10))\n\nplt.subplot(1, 2, 1)\nplt.suptitle('Optimizer : Adam, Loss : Binary CrossEntropy', fontsize=10)\nplt.ylabel('Loss', fontsize=16)\nplt.plot(history.history['loss'], label='ViT Training Loss')\nplt.legend(loc='upper right')\n\nplt.subplot(1, 2, 2)\nplt.ylabel('Loss', fontsize=16)\nplt.plot(cnnhistory.history['loss'], label='CNN Training Loss', c = 'darkred')\n\nplt.legend(loc='upper right')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Notes about Frequency Domain modeling\n\n* As expected the CNN model could converge faster 3x than the ViT model as the available dataset size isn't the ideal for such architecture(we's talking about 600 instances here) which is based on vision transformers which in turn needs more data than CNN to work properly. \n\n* The model loss curve is descending but it doesn't mean that the model is learning well, that's why further INVESTIGATION and IMPROVEMENTS shall be done on this work to find out if the imbalanced classes is the main issue here or if we need to try feature extraction techniques(noise cancelation filters, etc.) other than using the SFT's available. One of the possible improvements here is to use pre-trained model and only fine tune it, this shall overcome data limitation and other issues.","metadata":{}}]}