{"cells":[{"metadata":{},"cell_type":"markdown","source":"# Version\n* `v13`: Fold4\n* `v12`: Fold3\n* `v10`: Fold2\n* `v09`: Fold1\n* `v03`: Fold0"},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.execute_input":"2021-01-01T09:44:43.843489Z","iopub.status.busy":"2021-01-01T09:44:43.842712Z","iopub.status.idle":"2021-01-01T09:44:53.448523Z","shell.execute_reply":"2021-01-01T09:44:53.447971Z"},"papermill":{"duration":9.633907,"end_time":"2021-01-01T09:44:53.448657","exception":false,"start_time":"2021-01-01T09:44:43.81475","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"!pip install --upgrade seaborn","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:44:53.50848Z","iopub.status.busy":"2021-01-01T09:44:53.50769Z","iopub.status.idle":"2021-01-01T09:44:54.403472Z","shell.execute_reply":"2021-01-01T09:44:54.402433Z"},"papermill":{"duration":0.926929,"end_time":"2021-01-01T09:44:54.403588","exception":false,"start_time":"2021-01-01T09:44:53.476659","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"import numpy as np, pandas as pd\nfrom glob import glob\nimport shutil, os\nimport matplotlib.pyplot as plt\nfrom sklearn.model_selection import GroupKFold\nfrom tqdm.notebook import tqdm\nimport seaborn as sns","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"dim = '512' #512, 256, 'original'\nfold = 4","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:44:54.468231Z","iopub.status.busy":"2021-01-01T09:44:54.467706Z","iopub.status.idle":"2021-01-01T09:44:54.690894Z","shell.execute_reply":"2021-01-01T09:44:54.69183Z"},"papermill":{"duration":0.262045,"end_time":"2021-01-01T09:44:54.691965","exception":false,"start_time":"2021-01-01T09:44:54.42992","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"train_df = pd.read_csv(f'../input/vinbigdata-{dim}-image-dataset/vinbigdata/train.csv')\n# train_df = pd.read_csv(f'../input/vinbigdata-512-image-dataset/vinbigdata/train.csv')\n\ntrain_df.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:44:54.7506Z","iopub.status.busy":"2021-01-01T09:44:54.749926Z","iopub.status.idle":"2021-01-01T09:44:54.80575Z","shell.execute_reply":"2021-01-01T09:44:54.804838Z"},"papermill":{"duration":0.086788,"end_time":"2021-01-01T09:44:54.805857","exception":false,"start_time":"2021-01-01T09:44:54.719069","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"train_df['image_path'] = f'/kaggle/input/vinbigdata-{dim}-image-dataset/vinbigdata/train/'+train_df.image_id+('.png' if dim!='original' else '.jpg')\ntrain_df.head()","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.027478,"end_time":"2021-01-01T09:44:54.861374","exception":false,"start_time":"2021-01-01T09:44:54.833896","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Only 14 Class"},{"metadata":{"trusted":true},"cell_type":"code","source":"without_mass=train_df[train_df.class_id!=8]\n\nwithout_mass_files = []\nwithout_mass_files += list(without_mass.image_path.unique())","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:44:54.922292Z","iopub.status.busy":"2021-01-01T09:44:54.921364Z","iopub.status.idle":"2021-01-01T09:44:54.943995Z","shell.execute_reply":"2021-01-01T09:44:54.943575Z"},"papermill":{"duration":0.05543,"end_time":"2021-01-01T09:44:54.944088","exception":false,"start_time":"2021-01-01T09:44:54.888658","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"train_df = train_df[train_df.class_id==8].reset_index(drop = True)","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.052492,"end_time":"2021-01-01T09:47:56.110766","exception":false,"start_time":"2021-01-01T09:47:56.058274","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Split"},{"metadata":{"trusted":true},"cell_type":"code","source":"!pip install ensemble_boxes","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:47:56.234311Z","iopub.status.busy":"2021-01-01T09:47:56.233425Z","iopub.status.idle":"2021-01-01T09:47:56.297206Z","shell.execute_reply":"2021-01-01T09:47:56.297652Z"},"papermill":{"duration":0.134603,"end_time":"2021-01-01T09:47:56.297774","exception":false,"start_time":"2021-01-01T09:47:56.163171","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"gkf = GroupKFold(n_splits = 5)\ntrain_df['fold'] = -1\nfor fold, (train_idx, val_idx) in enumerate(gkf.split(train_df, groups = train_df.image_id.tolist())):\n train_df.loc[val_idx, 'fold'] = fold\ntrain_df.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:47:56.420454Z","iopub.status.busy":"2021-01-01T09:47:56.419355Z","iopub.status.idle":"2021-01-01T09:47:56.443157Z","shell.execute_reply":"2021-01-01T09:47:56.443661Z"},"papermill":{"duration":0.086817,"end_time":"2021-01-01T09:47:56.443789","exception":false,"start_time":"2021-01-01T09:47:56.356972","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"train_files = []\nval_files = []\nval_files += list(train_df[train_df.fold==fold].image_path.unique())\ntrain_files += list(train_df[train_df.fold!=fold].image_path.unique())\nlen(train_files), len(val_files)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# os.makedirs('/kaggle/working/vinbigdata/labels/train', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/labels/val', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/images/train', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/images/val', exist_ok = True)\n# label_dir = '/kaggle/input/vinbigdata-yolo-labels-dataset/labels'","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"import os.path as osp\nfrom path import Path\nfrom collections import Counter\nimport cv2\nfrom ensemble_boxes import *","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"imagepaths = train_df['image_path'].unique()\ntrain_annotations=train_df","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train_annotations['area']=((train_annotations['x_max']-train_annotations['x_min'])/train_annotations['width'])*((train_annotations['y_max']-train_annotations['y_min'])/train_annotations['height'])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# img_array = cv2.imread('/kaggle/input/vinbigdata-512-image-dataset/vinbigdata/train/d3637a1935a905b3c326af31389cb846.png')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# def Create_nms_box_txt(desktop_path,name):\n# iou_thr = 0.5\n# skip_box_thr = 0.0001\n# viz_images = []\n# # image_basename = Path(path).stem\n# image_basename = name\n# # print(f\"(\\'{image_basename}\\', \\'{path}\\')\")\n# img_annotations = train_annotations[train_annotations.image_id==image_basename][train_annotations.class_id==8]\n\n# boxes_viz = img_annotations[['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().tolist()\n# labels_viz = img_annotations['class_id'].to_numpy().tolist()\n\n# print(\"Bboxes before nms:\\n\", boxes_viz)\n# print(\"Labels before nms:\\n\", labels_viz)\n\n# boxes_list = []\n# scores_list = []\n# labels_list = []\n# weights = []\n\n# boxes_single = []\n# labels_single = []\n\n# cls_ids = img_annotations['class_id'].unique().tolist()\n# count_dict = Counter(img_annotations['class_id'].tolist())\n# print(count_dict)\n\n# for cid in cls_ids: \n# ## Performing Fusing operation only for multiple bboxes with the same label\n# if count_dict[cid]==1:\n# labels_single.append(cid)\n# boxes_single.append(img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().squeeze().tolist())\n\n# else:\n# cls_list =img_annotations[img_annotations.class_id==cid]['class_id'].tolist()\n# labels_list.append(cls_list)\n# bbox = img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy()\n\n# ## Normalizing Bbox by Image Width and Height\n# bbox = bbox/(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n\n\n# bbox = np.clip(bbox, 0, 1)\n# boxes_list.append(bbox.tolist())\n\n# scores_list.append(np.ones(len(cls_list)).tolist())\n\n# weights.append(1)\n\n \n# # Perform NMS\n# if len(boxes_list)==0:\n# boxes=boxes_single\n# box_labels=labels_single\n# print(\"Bboxes after nms:\\n\", boxes)\n# print(\"Labels after nms:\\n\", box_labels)\n \n# count_dict = Counter(box_labels)\n# print(count_dict)\n\n# text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])\n \n# else:\n# boxes, scores, box_labels = nms(boxes_list, scores_list, labels_list, weights=weights,\n# iou_thr=iou_thr)\n\n\n# #img_array.shape[1]是宽度\n# boxes = boxes*(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n# boxes = boxes.round(1).tolist()\n# box_labels = box_labels.astype(int).tolist()\n\n# boxes.extend(boxes_single)\n# box_labels.extend(labels_single)\n\n# print(\"Bboxes after nms:\\n\", boxes)\n# print(\"Labels after nms:\\n\", box_labels)\n\n# count_dict = Counter(box_labels)\n# print(count_dict)\n\n# text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# iou_thr = 0.5\n# skip_box_thr = 0.0001\n# viz_images = []\n# for i, path in tqdm(enumerate(imagepaths[5:6])):\n# image_basename = Path(path).stem\n# print(f\"(\\'{image_basename}\\', \\'{path}\\')\")\n# img_annotations = train_annotations[train_annotations.image_id==image_basename]\n\n# boxes_viz = img_annotations[['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().tolist()\n# labels_viz = img_annotations['class_id'].to_numpy().tolist()\n\n# print(\"Bboxes before nms:\\n\", boxes_viz)\n# print(\"Labels before nms:\\n\", labels_viz)\n\n# boxes_list = []\n# scores_list = []\n# labels_list = []\n# weights = []\n\n# boxes_single = []\n# labels_single = []\n\n# cls_ids = img_annotations['class_id'].unique().tolist()\n# count_dict = Counter(img_annotations['class_id'].tolist())\n# print(count_dict)\n\n# for cid in cls_ids: \n# ## Performing Fusing operation only for multiple bboxes with the same label\n# if count_dict[cid]==1:\n# labels_single.append(cid)\n# boxes_single.append(img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().squeeze().tolist())\n\n# else:\n# cls_list =img_annotations[img_annotations.class_id==cid]['class_id'].tolist()\n# labels_list.append(cls_list)\n# bbox = img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy()\n\n# ## Normalizing Bbox by Image Width and Height\n# bbox = bbox/(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n\n\n# bbox = np.clip(bbox, 0, 1)\n# boxes_list.append(bbox.tolist())\n\n# scores_list.append(np.ones(len(cls_list)).tolist())\n\n# weights.append(1)\n\n\n# # Perform NMS\n# boxes, scores, box_labels = nms(boxes_list, scores_list, labels_list, weights=weights,\n# iou_thr=iou_thr)\n \n# print(\"Bboxes without multipy:\\n\", boxes)\n\n# #img_array.shape[1]是宽度\n# boxes = boxes*(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n# boxes = boxes.round(1).tolist()\n# box_labels = box_labels.astype(int).tolist()\n\n# boxes.extend(boxes_single)\n# box_labels.extend(labels_single)\n\n# print(\"Bboxes after nms:\\n\", boxes)\n# print(\"Labels after nms:\\n\", box_labels)\n\n# count_dict = Counter(box_labels)\n# print(count_dict)\n\n# text_create('./',image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train_annotations=train_annotations[train_annotations.area<0.026]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train_annotations","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def Create_softnms_box_txt(desktop_path,name):\n iou_thr = 0.5\n skip_box_thr = 0.0001\n viz_images = []\n sigma = 0.1\n# image_basename = Path(path).stem\n image_basename = name\n# print(f\"(\\'{image_basename}\\', \\'{path}\\')\")\n img_annotations = train_annotations[train_annotations.image_id==image_basename][train_annotations.class_id==8]\n\n boxes_viz = img_annotations[['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().tolist()\n labels_viz_raw = img_annotations['class_id'].to_numpy().tolist()\n labels_viz = [0 if wd == 8 else wd for wd in labels_viz_raw]\n \n print('boxes_viz',boxes_viz)\n \n if(len(boxes_viz)==0):\n text_create(desktop_path,image_basename,[],[],0,0)\n return None\n\n print('没有return')\n \n print(\"Bboxes before nms:\\n\", boxes_viz)\n print(\"Labels before nms:\\n\", labels_viz)\n\n boxes_list = []\n scores_list = []\n labels_list = []\n weights = []\n\n boxes_single = []\n labels_single = []\n\n cls_ids = img_annotations['class_id'].unique().tolist()\n count_dict = Counter(img_annotations['class_id'].tolist())\n print(count_dict)\n\n for cid in cls_ids: \n ## Performing Fusing operation only for multiple bboxes with the same label\n if count_dict[cid]==1:\n labels_single.append(cid)\n boxes_single.append(img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().squeeze().tolist())\n\n else:\n cls_list =img_annotations[img_annotations.class_id==cid]['class_id'].tolist()\n labels_list.append(cls_list)\n bbox = img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy()\n\n ## Normalizing Bbox by Image Width and Height\n bbox = bbox/(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n\n\n bbox = np.clip(bbox, 0, 1)\n boxes_list.append(bbox.tolist())\n\n scores_list.append(np.ones(len(cls_list)).tolist())\n\n weights.append(1)\n\n \n\n # Perform NMS\n if len(boxes_list)==0:\n boxes=boxes_single\n box_labels=labels_single\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n \n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])\n \n else:\n boxes, scores, box_labels = soft_nms(boxes_list, scores_list, labels_list, weights=weights,\n iou_thr=iou_thr)\n\n\n #img_array.shape[1]是宽度\n boxes = boxes*(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n boxes = boxes.round(1).tolist()\n box_labels = box_labels.astype(int).tolist()\n\n boxes.extend(boxes_single)\n box_labels.extend(labels_single)\n\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n\n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def Create_non_maximum_weighted_box_txt(desktop_path,name):\n iou_thr = 0.5\n skip_box_thr = 0.0001\n viz_images = []\n# image_basename = Path(path).stem\n image_basename = name\n# print(f\"(\\'{image_basename}\\', \\'{path}\\')\")\n img_annotations = train_annotations[train_annotations.image_id==image_basename][train_annotations.class_id==8]\n\n boxes_viz = img_annotations[['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().tolist()\n labels_viz = img_annotations['class_id'].to_numpy().tolist()\n\n print(\"Bboxes before nms:\\n\", boxes_viz)\n print(\"Labels before nms:\\n\", labels_viz)\n\n boxes_list = []\n scores_list = []\n labels_list = []\n weights = []\n\n boxes_single = []\n labels_single = []\n\n cls_ids = img_annotations['class_id'].unique().tolist()\n count_dict = Counter(img_annotations['class_id'].tolist())\n print(count_dict)\n\n for cid in cls_ids: \n ## Performing Fusing operation only for multiple bboxes with the same label\n if count_dict[cid]==1:\n labels_single.append(cid)\n boxes_single.append(img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().squeeze().tolist())\n\n else:\n cls_list =img_annotations[img_annotations.class_id==cid]['class_id'].tolist()\n labels_list.append(cls_list)\n bbox = img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy()\n\n ## Normalizing Bbox by Image Width and Height\n bbox = bbox/(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n\n\n bbox = np.clip(bbox, 0, 1)\n boxes_list.append(bbox.tolist())\n\n scores_list.append(np.ones(len(cls_list)).tolist())\n\n weights.append(1)\n\n \n # Perform NMS\n if len(boxes_list)==0:\n boxes=boxes_single\n box_labels=labels_single\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n \n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])\n \n else:\n boxes, scores, box_labels = non_maximum_weighted(boxes_list, scores_list, labels_list, weights=weights,\n iou_thr=iou_thr)\n\n\n #img_array.shape[1]是宽度\n boxes = boxes*(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n boxes = boxes.round(1).tolist()\n box_labels = box_labels.astype(int).tolist()\n\n boxes.extend(boxes_single)\n box_labels.extend(labels_single)\n\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n\n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# os.makedirs('/kaggle/working/vinbigdata/labels/train', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/labels/val', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/images/train', exist_ok = True)\n# os.makedirs('/kaggle/working/vinbigdata/images/val', exist_ok = True)\n# label_dir = '/kaggle/input/vinbigdata-yolo-labels-dataset/labels'","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# # shutil.copy(file, '/kaggle/working/vinbigdata/images/train')\n\n# img_annotations = train_df[train_df.image_id=='47ed17dcb2cbeec15182ed335a8b5a9e'][train_df.class_id==8]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# img_annotations","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def Create_weighted_boxes_fusion_box_txt(desktop_path,name):\n iou_thr = 0.5\n skip_box_thr = 0.0001\n viz_images = []\n# image_basename = Path(path).stem\n image_basename = name\n# print(f\"(\\'{image_basename}\\', \\'{path}\\')\")\n img_annotations = train_annotations[train_annotations.image_id==image_basename][train_df.class_id==8]\n\n boxes_viz = img_annotations[['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().tolist()\n labels_viz_raw = img_annotations['class_id'].to_numpy().tolist()\n labels_viz = [0 if wd == 8 else wd for wd in labels_viz_raw]\n\n print(\"Bboxes before nms:\\n\", boxes_viz)\n print(\"Labels before nms:\\n\", labels_viz)\n\n boxes_list = []\n scores_list = []\n labels_list = []\n weights = []\n\n boxes_single = []\n labels_single = []\n\n cls_ids = img_annotations['class_id'].unique().tolist()\n count_dict = Counter(img_annotations['class_id'].tolist())\n print(count_dict)\n\n for cid in cls_ids: \n ## Performing Fusing operation only for multiple bboxes with the same label\n if count_dict[cid]==1:\n labels_single.append(cid)\n boxes_single.append(img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy().squeeze().tolist())\n\n else:\n cls_list =img_annotations[img_annotations.class_id==cid]['class_id'].tolist()\n labels_list.append(cls_list)\n bbox = img_annotations[img_annotations.class_id==cid][['x_min', 'y_min', 'x_max', 'y_max']].to_numpy()\n\n ## Normalizing Bbox by Image Width and Height\n bbox = bbox/(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n\n\n bbox = np.clip(bbox, 0, 1)\n boxes_list.append(bbox.tolist())\n\n scores_list.append(np.ones(len(cls_list)).tolist())\n\n weights.append(1)\n\n \n # Perform NMS\n if len(boxes_list)==0:\n boxes=boxes_single\n box_labels=labels_single\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n \n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])\n \n else:\n boxes, scores, box_labels = weighted_boxes_fusion(boxes_list, scores_list, labels_list, weights=weights,\n iou_thr=iou_thr)\n\n\n #img_array.shape[1]是宽度\n boxes = boxes*(img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"], img_annotations.iloc[0][\"width\"], img_annotations.iloc[0][\"height\"])\n boxes = boxes.round(1).tolist()\n box_labels = box_labels.astype(int).tolist()\n\n boxes.extend(boxes_single)\n box_labels.extend(labels_single)\n\n print(\"Bboxes after nms:\\n\", boxes)\n print(\"Labels after nms:\\n\", box_labels)\n\n count_dict = Counter(box_labels)\n print(count_dict)\n\n text_create(desktop_path,image_basename,boxes,box_labels,img_annotations.iloc[0][\"width\"],img_annotations.iloc[0][\"height\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def text_create(desktop_path,name, boxes,box_labels,w,h):\n \n \n full_path = os.path.join(desktop_path, name+'.txt') # 也可以创建一个.doc的word文档\n print('full_path',full_path)\n file = open(full_path, 'w')\n \n if(len(boxes)==0):\n file.close()\n else:\n dw = 1. / (w)\n dh = 1. / (h)\n\n for i in range(len(boxes)):\n\n\n x = (boxes[i][0] + boxes[i][2]) / 2.0\n y = (boxes[i][1] + boxes[i][3]) / 2.0\n w = boxes[i][2] - boxes[i][0]\n h = boxes[i][3] - boxes[i][1]\n\n\n x = x * dw\n w = w * dw\n y = y * dh\n h = h * dh\n\n\n # file.write(str(box_labels[i])+ ' '+ str(x)+ ' '+ str(y)+ ' '+ str(w)+ ' '+ str(h)+ ' '+ '\\n') \n file.write(str(0)+ ' '+ str(x)+ ' '+ str(y)+ ' '+ str(w)+ ' '+ str(h)+ ' '+ '\\n')\n print('录入'+str(0)+ ' '+ str(x)+ ' '+ str(y)+ ' '+ str(w)+ ' '+ str(h)+ ' ')\n file.close()","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.083752,"end_time":"2021-01-01T09:47:56.584924","exception":false,"start_time":"2021-01-01T09:47:56.501172","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Copying Files"},{"metadata":{"trusted":true},"cell_type":"code","source":"train_files","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"os.makedirs('/kaggle/working/vinbigdata/labels/train', exist_ok = True)\nos.makedirs('/kaggle/working/vinbigdata/labels/val', exist_ok = True)\nos.makedirs('/kaggle/working/vinbigdata/images/train', exist_ok = True)\nos.makedirs('/kaggle/working/vinbigdata/images/val', exist_ok = True)\nlabel_dir = '/kaggle/input/vinbigdata-yolo-labels-dataset/labels'\nfor file in tqdm(train_files):\n shutil.copy(file, '/kaggle/working/vinbigdata/images/train')\n filename = file.split('/')[-1].split('.')[0]\n \n # nms stuff\n print(filename)\n Create_softnms_box_txt('/kaggle/working/vinbigdata/labels/train',filename)\n \n# shutil.copy(os.path.join(label_dir, filename+'.txt'), '/kaggle/working/vinbigdata/labels/train')\n \nfor file in tqdm(val_files):\n shutil.copy(file, '/kaggle/working/vinbigdata/images/val')\n filename = file.split('/')[-1].split('.')[0]\n \n # nms stuff\n Create_softnms_box_txt('/kaggle/working/vinbigdata/labels/val',filename)\n# shutil.copy(os.path.join(label_dir, filename+'.txt'), '/kaggle/working/vinbigdata/labels/val')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"import os\npath = os.getcwd()#获取当前路径\n# print(path)\n\nall_files = [f for f in os.listdir('/kaggle/working/vinbigdata/labels/train' )]#输出根path下的所有文件名到一个列表中\n# all_files = [f for f in os.listdir(path )]#输出根path下的所有文件名到一个列表中\n#对各个文件进行处理\nprint(all_files)","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.068822,"end_time":"2021-01-01T09:50:01.458337","exception":false,"start_time":"2021-01-01T09:50:01.389515","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Get Class Name"},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:50:01.595454Z","iopub.status.busy":"2021-01-01T09:50:01.594289Z","iopub.status.idle":"2021-01-01T09:50:01.60074Z","shell.execute_reply":"2021-01-01T09:50:01.601395Z"},"papermill":{"duration":0.082234,"end_time":"2021-01-01T09:50:01.601574","exception":false,"start_time":"2021-01-01T09:50:01.51934","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"class_ids, class_names = list(zip(*set(zip(train_df.class_id, train_df.class_name))))\nclasses = list(np.array(class_names)[np.argsort(class_ids)])\nclasses = list(map(lambda x: str(x), classes))\nclasses","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.056257,"end_time":"2021-01-01T09:50:01.716608","exception":false,"start_time":"2021-01-01T09:50:01.660351","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# [YOLOv5](https://github.com/ultralytics/yolov5)\n\n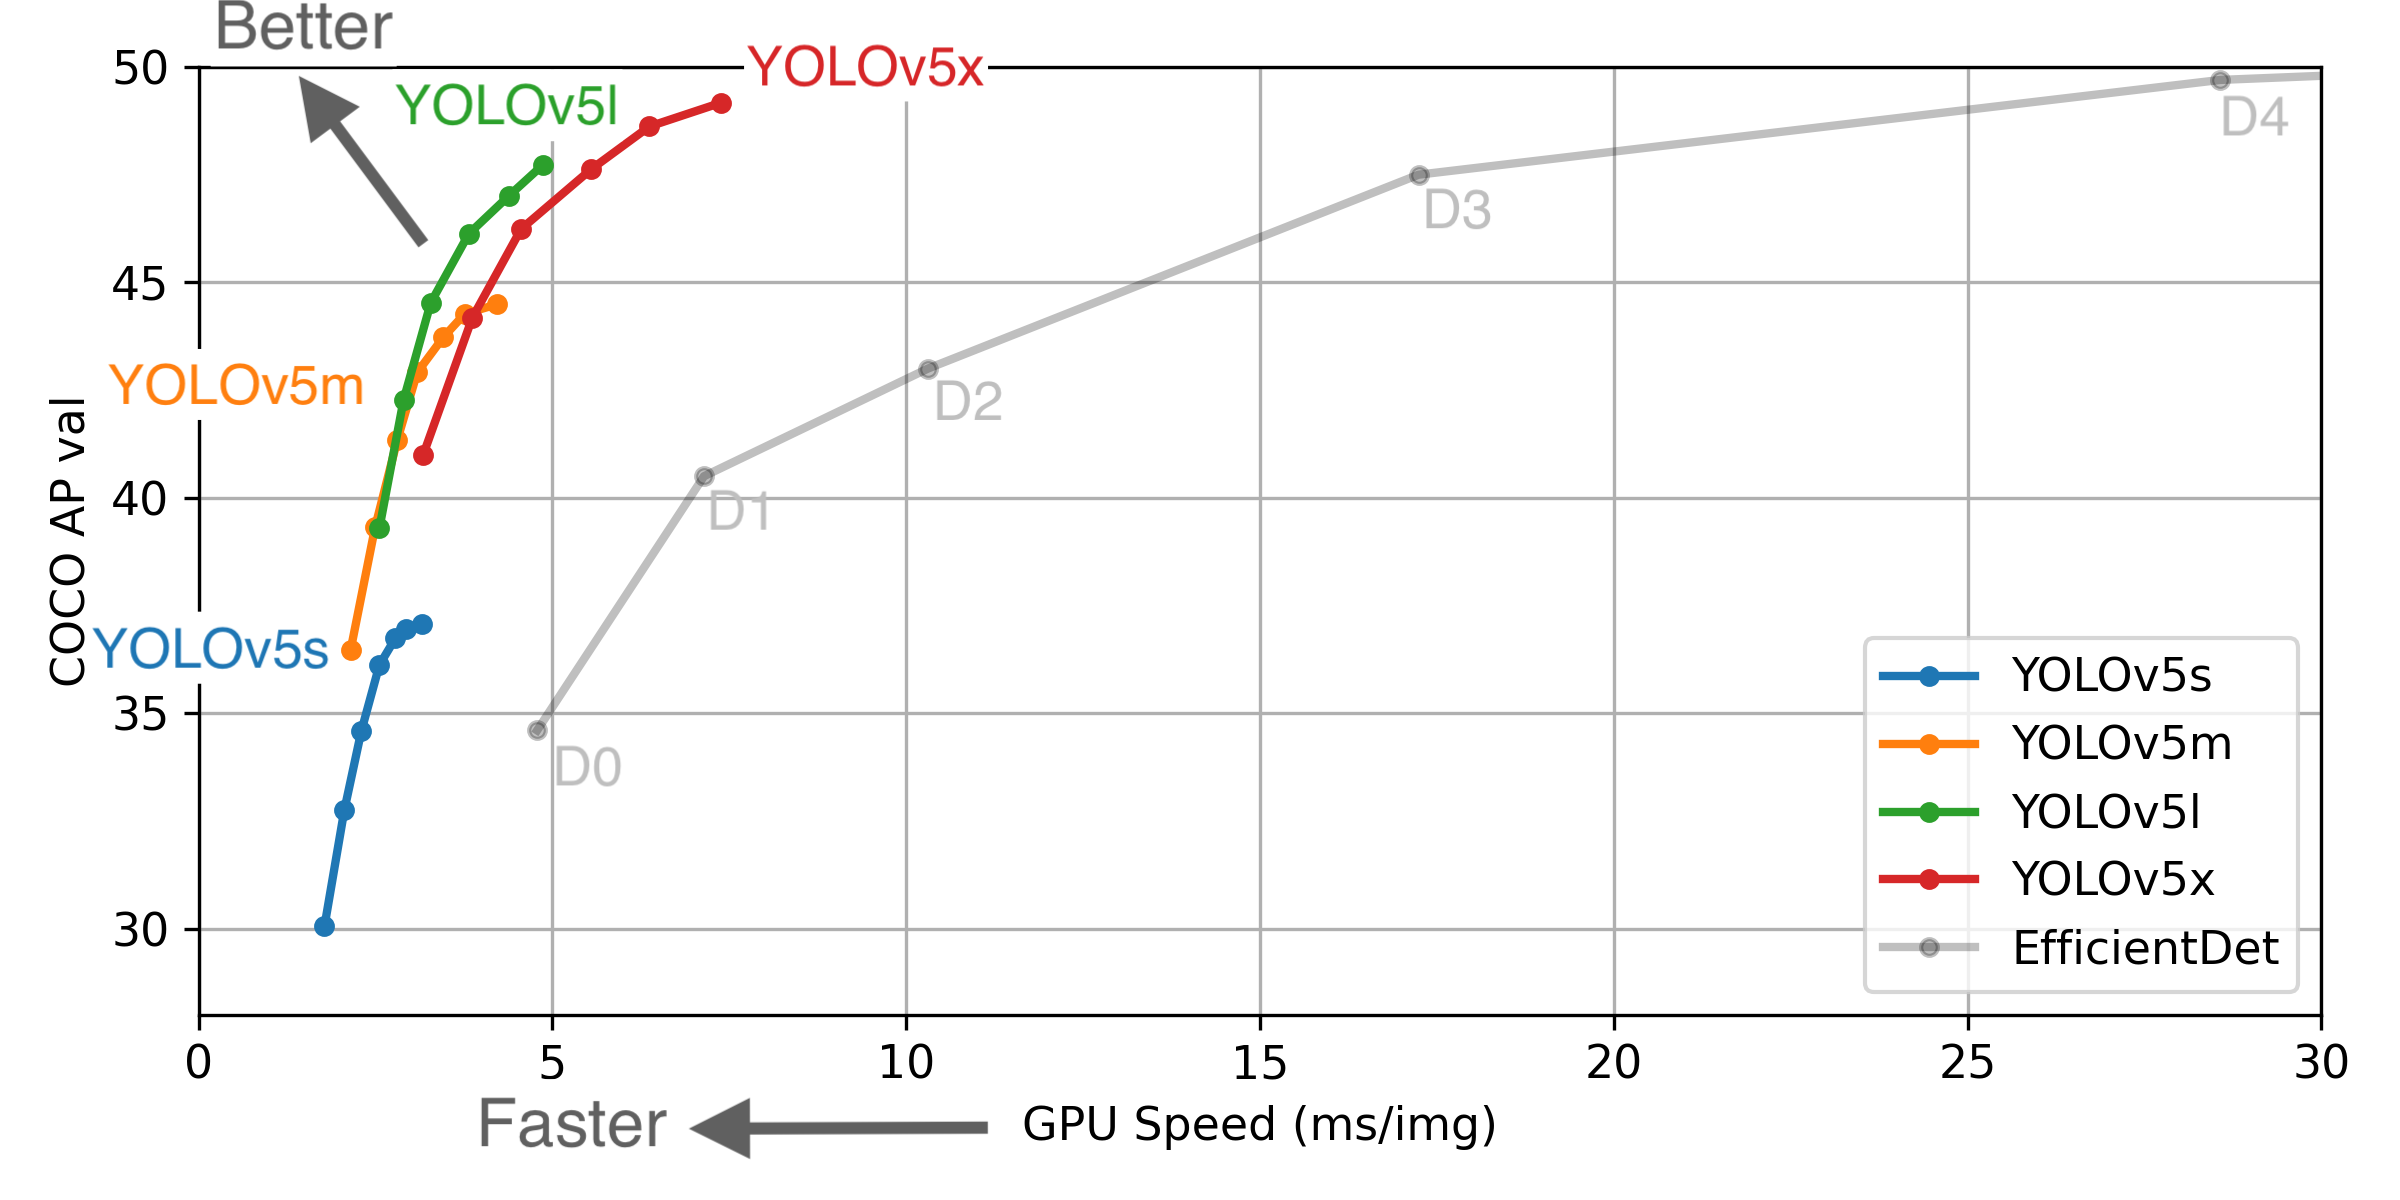"},{"metadata":{"papermill":{"duration":0.055699,"end_time":"2021-01-01T09:50:01.82747","exception":false,"start_time":"2021-01-01T09:50:01.771771","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# YOLOv5 Stuff"},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:50:01.950234Z","iopub.status.busy":"2021-01-01T09:50:01.949285Z","iopub.status.idle":"2021-01-01T09:50:01.995866Z","shell.execute_reply":"2021-01-01T09:50:01.996316Z"},"papermill":{"duration":0.113001,"end_time":"2021-01-01T09:50:01.996448","exception":false,"start_time":"2021-01-01T09:50:01.883447","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"from os import listdir\nfrom os.path import isfile, join\nimport yaml\n\ncwd = '/kaggle/working/'\n\nwith open(join( cwd , 'train.txt'), 'w') as f:\n for path in glob('/kaggle/working/vinbigdata/images/train/*'):\n f.write(path+'\\n')\n \nwith open(join( cwd , 'val.txt'), 'w') as f:\n for path in glob('/kaggle/working/vinbigdata/images/val/*'):\n f.write(path+'\\n')\n\ndata = dict(\n train = join( cwd , 'train.txt') ,\n val = join( cwd , 'val.txt' ),\n nc = 1,\n names = classes\n )\n\nwith open(join( cwd , 'vinbigdata.yaml'), 'w') as outfile:\n yaml.dump(data, outfile, default_flow_style=False)\n\nf = open(join( cwd , 'vinbigdata.yaml'), 'r')\nprint('\\nyaml:')\nprint(f.read())","execution_count":null,"outputs":[]},{"metadata":{"_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","execution":{"iopub.execute_input":"2021-01-01T09:50:02.170487Z","iopub.status.busy":"2021-01-01T09:50:02.169672Z","iopub.status.idle":"2021-01-01T09:50:08.782533Z","shell.execute_reply":"2021-01-01T09:50:08.783883Z"},"papermill":{"duration":6.702428,"end_time":"2021-01-01T09:50:08.784153","exception":false,"start_time":"2021-01-01T09:50:02.081725","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"# https://www.kaggle.com/ultralytics/yolov5\n# !git clone https://github.com/ultralytics/yolov5 # clone repo\n# %cd yolov5\nshutil.copytree('/kaggle/input/yolov5-official-v31-dataset/yolov5', '/kaggle/working/yolov5')\nos.chdir('/kaggle/working/yolov5')\n%pip install -qr requirements.txt # install dependencies\n\nimport torch\nfrom IPython.display import Image, clear_output # to display images\n\nclear_output()\nprint('Setup complete. Using torch %s %s' % (torch.__version__, torch.cuda.get_device_properties(0) if torch.cuda.is_available() else 'CPU'))","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:50:08.996106Z","iopub.status.busy":"2021-01-01T09:50:08.995246Z","iopub.status.idle":"2021-01-01T09:50:19.303278Z","shell.execute_reply":"2021-01-01T09:50:19.302769Z"},"papermill":{"duration":10.410768,"end_time":"2021-01-01T09:50:19.303402","exception":false,"start_time":"2021-01-01T09:50:08.892634","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"!python detect.py --weights yolov5s.pt --img 640 --conf 0.25 --source data/images/\nImage(filename='runs/detect/exp/zidane.jpg', width=600)","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.064911,"end_time":"2021-01-01T09:50:19.435746","exception":false,"start_time":"2021-01-01T09:50:19.370835","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## Pretrained Checkpoints:\n\n| Model | APval | APtest | AP50 | SpeedGPU | FPSGPU || params | FLOPS |\n|---------- |------ |------ |------ | -------- | ------| ------ |------ | :------: |\n| [YOLOv5s](https://github.com/ultralytics/yolov5/releases/tag/v3.0) | 37.0 | 37.0 | 56.2 | **2.4ms** | **416** || 7.5M | 13.2B\n| [YOLOv5m](https://github.com/ultralytics/yolov5/releases/tag/v3.0) | 44.3 | 44.3 | 63.2 | 3.4ms | 294 || 21.8M | 39.4B\n| [YOLOv5l](https://github.com/ultralytics/yolov5/releases/tag/v3.0) | 47.7 | 47.7 | 66.5 | 4.4ms | 227 || 47.8M | 88.1B\n| [YOLOv5x](https://github.com/ultralytics/yolov5/releases/tag/v3.0) | **49.2** | **49.2** | **67.7** | 6.9ms | 145 || 89.0M | 166.4B\n| | | | | | || |\n| [YOLOv5x](https://github.com/ultralytics/yolov5/releases/tag/v3.0) + TTA|**50.8**| **50.8** | **68.9** | 25.5ms | 39 || 89.0M | 354.3B\n| | | | | | || |\n| [YOLOv3-SPP](https://github.com/ultralytics/yolov5/releases/tag/v3.0) | 45.6 | 45.5 | 65.2 | 4.5ms | 222 || 63.0M | 118.0B"},{"metadata":{"papermill":{"duration":0.064016,"end_time":"2021-01-01T09:50:19.564859","exception":false,"start_time":"2021-01-01T09:50:19.500843","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Selecting Models\nIn this notebok I'm using `v5s`. To select your prefered model just replace `--cfg models/yolov5s.yaml --weights yolov5s.pt` with the following command:\n* `v5s` : `--cfg models/yolov5s.yaml --weights yolov5s.pt`\n* `v5m` : `--cfg models/yolov5m.yaml --weights yolov5m.pt`\n* `v5l` : `--cfg models/yolov5l.yaml --weights yolov5l.pt`\n* `v5x` : `--cfg models/yolov5x.yaml --weights yolov5x.pt`"},{"metadata":{"papermill":{"duration":0.064553,"end_time":"2021-01-01T09:50:19.6938","exception":false,"start_time":"2021-01-01T09:50:19.629247","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Train"},{"metadata":{"trusted":true},"cell_type":"code","source":"hyp_adjust = {'optimizer': 'SGD', # 优化器['adam', 'SGD', None] if none, default is SGD\n 'lr0': 0.01, # 学习率initial learning rate (SGD=1E-2, Adam=1E-3)\n 'momentum': 0.937, # 学习率动量SGD momentum/Adam beta1\n 'weight_decay': 5e-4, # 权重衰减系数optimizer weight decay\n 'giou': 0.05, # giou损失的系数giou loss gain\n 'cls': 0.58, # 分类损失的系数cls loss gain\n 'cls_pw': 1.0, # 分类BCELoss中正样本的权重cls BCELoss positive_weight\n 'obj': 1.0, # 有无物体损失的系数obj loss gain (*=img_size/320 if img_size != 320)\n 'obj_pw': 1.0, # 有无物体BCELoss中正样本的权重obj BCELoss positive_weight\n 'iou_t': 0.20, # 标签与anchors的iou阈值iou training threshold\n 'anchor_t': 4.0, # 标签的长h宽w/anchor的长h_a宽w_a阈值, 即h/h_a, w/w_a都要在(1/4, 4)之间anchor-multiple threshold\n 'fl_gamma': 0.0, # focal loss gamma, 设为0则表示不使用focal loss(efficientDet default is gamma=1.5)\n # 下面是一些数据增强的系数, 包括颜色空间和图片空间\n 'hsv_h': 0.014, # image HSV-Hue augmentation (fraction)\n 'hsv_s': 0.68, # image HSV-Saturation augmentation (fraction)\n 'hsv_v': 0.36, # image HSV-Value augmentation (fraction)\n 'degrees': 0.0, # image rotation (+/- deg)\n 'translate': 0.0, # image translation (+/- fraction)\n 'scale': 0.5, # image scale (+/- gain)\n 'shear': 0.0}","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T09:50:19.916161Z","iopub.status.busy":"2021-01-01T09:50:19.915216Z","iopub.status.idle":"2021-01-01T15:22:16.288743Z","shell.execute_reply":"2021-01-01T15:22:16.289579Z"},"papermill":{"duration":19916.498298,"end_time":"2021-01-01T15:22:16.289734","exception":false,"start_time":"2021-01-01T09:50:19.791436","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"# # !WANDB_MODE=\"dryrun\" python train.py --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --nosave --cache \n!WANDB_MODE=\"dryrun\" python train.py --img 640 --batch 16 --epochs 30 --data /kaggle/working/vinbigdata.yaml --weights yolov5s.pt --cache ","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":4.919442,"end_time":"2021-01-01T15:22:26.398681","exception":false,"start_time":"2021-01-01T15:22:21.479239","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Class Distribution"},{"metadata":{"trusted":true},"cell_type":"code","source":"\n!pip install matplotlib==3.1.3","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:22:36.714816Z","iopub.status.busy":"2021-01-01T15:22:36.713892Z","iopub.status.idle":"2021-01-01T15:22:37.752475Z","shell.execute_reply":"2021-01-01T15:22:37.752939Z"},"papermill":{"duration":6.511035,"end_time":"2021-01-01T15:22:37.753063","exception":false,"start_time":"2021-01-01T15:22:31.242028","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"plt.figure(figsize = (20,20))\nplt.axis('off')\nplt.imshow(plt.imread('runs/train/exp/labels_correlogram.jpg'));","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:22:47.848164Z","iopub.status.busy":"2021-01-01T15:22:47.847303Z","iopub.status.idle":"2021-01-01T15:22:48.613974Z","shell.execute_reply":"2021-01-01T15:22:48.614481Z"},"papermill":{"duration":5.977042,"end_time":"2021-01-01T15:22:48.614609","exception":false,"start_time":"2021-01-01T15:22:42.637567","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"plt.figure(figsize = (20,20))\nplt.axis('off')\nplt.imshow(plt.imread('runs/train/exp/labels.jpg'));","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":5.378338,"end_time":"2021-01-01T15:22:59.482837","exception":false,"start_time":"2021-01-01T15:22:54.104499","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Batch Image"},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:23:10.192425Z","iopub.status.busy":"2021-01-01T15:23:10.19175Z","iopub.status.idle":"2021-01-01T15:23:11.776947Z","shell.execute_reply":"2021-01-01T15:23:11.777415Z"},"papermill":{"duration":7.317416,"end_time":"2021-01-01T15:23:11.777544","exception":false,"start_time":"2021-01-01T15:23:04.460128","status":"completed"},"tags":[],"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"import matplotlib.pyplot as plt\nplt.figure(figsize = (15, 15))\nplt.imshow(plt.imread('runs/train/exp/train_batch0.jpg'))\n\nplt.figure(figsize = (15, 15))\nplt.imshow(plt.imread('runs/train/exp/train_batch1.jpg'))\n\nplt.figure(figsize = (15, 15))\nplt.imshow(plt.imread('runs/train/exp/train_batch2.jpg'))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# GT Vs Pred"},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:23:22.104906Z","iopub.status.busy":"2021-01-01T15:23:22.10403Z","iopub.status.idle":"2021-01-01T15:23:23.51416Z","shell.execute_reply":"2021-01-01T15:23:23.514596Z"},"papermill":{"duration":6.453975,"end_time":"2021-01-01T15:23:23.514717","exception":false,"start_time":"2021-01-01T15:23:17.060742","status":"completed"},"tags":[],"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"fig, ax = plt.subplots(3, 2, figsize = (2*5,3*5), constrained_layout = True)\nfor row in range(3):\n ax[row][0].imshow(plt.imread(f'runs/train/exp/test_batch{row}_labels.jpg'))\n ax[row][0].set_xticks([])\n ax[row][0].set_yticks([])\n ax[row][0].set_title(f'runs/train/exp/test_batch{row}_labels.jpg', fontsize = 12)\n \n ax[row][1].imshow(plt.imread(f'runs/train/exp/test_batch{row}_pred.jpg'))\n ax[row][1].set_xticks([])\n ax[row][1].set_yticks([])\n ax[row][1].set_title(f'runs/train/exp/test_batch{row}_pred.jpg', fontsize = 12)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# (Loss, Map) Vs Epoch"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"plt.figure(figsize=(30,15))\nplt.axis('off')\nplt.imshow(plt.imread('runs/train/exp/results.png'));","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Confusion Matrix"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"plt.figure(figsize=(30,15))\nplt.axis('off')\nplt.imshow(plt.imread('runs/train/exp/confusion_matrix.png'));","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":4.941983,"end_time":"2021-01-01T15:23:33.765831","exception":false,"start_time":"2021-01-01T15:23:28.823848","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Inference"},{"metadata":{"_kg_hide-output":true,"execution":{"iopub.execute_input":"2021-01-01T15:23:44.50211Z","iopub.status.busy":"2021-01-01T15:23:44.501304Z","iopub.status.idle":"2021-01-01T15:23:49.800287Z","shell.execute_reply":"2021-01-01T15:23:49.799352Z"},"papermill":{"duration":10.763143,"end_time":"2021-01-01T15:23:49.800461","exception":false,"start_time":"2021-01-01T15:23:39.037318","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"!python detect.py --weights 'runs/train/exp/weights/best.pt'\\\n--img 640\\\n--conf 0.15\\\n--iou 0.5\\\n--source /kaggle/working/vinbigdata/images/val\\\n--exist-ok","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":5.225725,"end_time":"2021-01-01T15:24:00.706026","exception":false,"start_time":"2021-01-01T15:23:55.480301","status":"completed"},"tags":[]},"cell_type":"markdown","source":"# Inference Plot"},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:24:10.963448Z","iopub.status.busy":"2021-01-01T15:24:10.962552Z","iopub.status.idle":"2021-01-01T15:24:11.210595Z","shell.execute_reply":"2021-01-01T15:24:11.211731Z"},"papermill":{"duration":5.31015,"end_time":"2021-01-01T15:24:11.211904","exception":false,"start_time":"2021-01-01T15:24:05.901754","status":"completed"},"tags":[],"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"import matplotlib.pyplot as plt\nfrom mpl_toolkits.axes_grid1 import ImageGrid\nimport numpy as np\nimport random\nimport cv2\nfrom glob import glob\nfrom tqdm import tqdm\n\nfiles = glob('runs/detect/exp/*')\nfor _ in range(3):\n row = 4\n col = 4\n grid_files = random.sample(files, row*col)\n images = []\n for image_path in tqdm(grid_files):\n img = cv2.cvtColor(cv2.imread(image_path), cv2.COLOR_BGR2RGB)\n images.append(img)\n\n fig = plt.figure(figsize=(col*5, row*5))\n grid = ImageGrid(fig, 111, # similar to subplot(111)\n nrows_ncols=(col, row), # creates 2x2 grid of axes\n axes_pad=0.05, # pad between axes in inch.\n )\n\n for ax, im in zip(grid, images):\n # Iterating over the grid returns the Axes.\n ax.imshow(im)\n ax.set_xticks([])\n ax.set_yticks([])\n plt.show()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2021-01-01T15:24:21.60059Z","iopub.status.busy":"2021-01-01T15:24:21.599598Z","iopub.status.idle":"2021-01-01T15:24:22.413063Z","shell.execute_reply":"2021-01-01T15:24:22.411761Z"},"papermill":{"duration":5.709202,"end_time":"2021-01-01T15:24:22.413173","exception":false,"start_time":"2021-01-01T15:24:16.703971","status":"completed"},"tags":[],"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true},"cell_type":"code","source":"# shutil.rmtree('/kaggle/working/vinbigdata')\n# shutil.rmtree('runs/detect')\n# for file in (glob('runs/train/exp/**/*.png', recursive = True)+glob('runs/train/exp/**/*.jpg', recursive = True)):\n# os.remove(file)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":4}